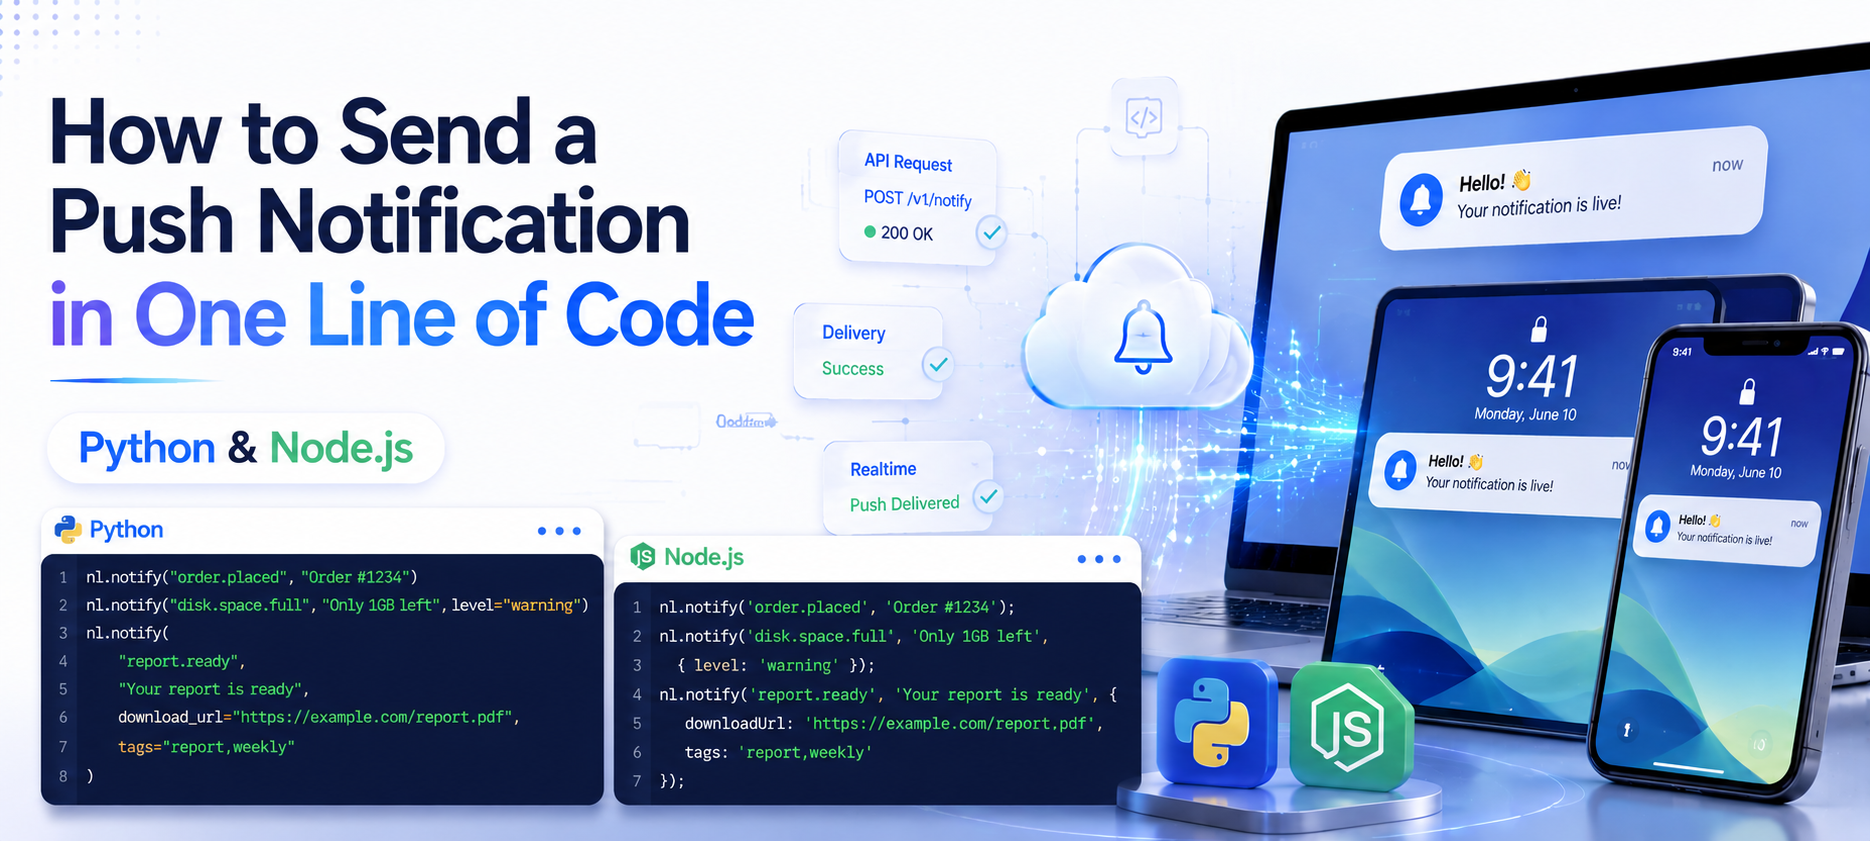
You don't need a notification server, a message queue, or a mobile push certificate headache. Here's how to send a real push notification to your phone from a Python or Node.js script in one line.
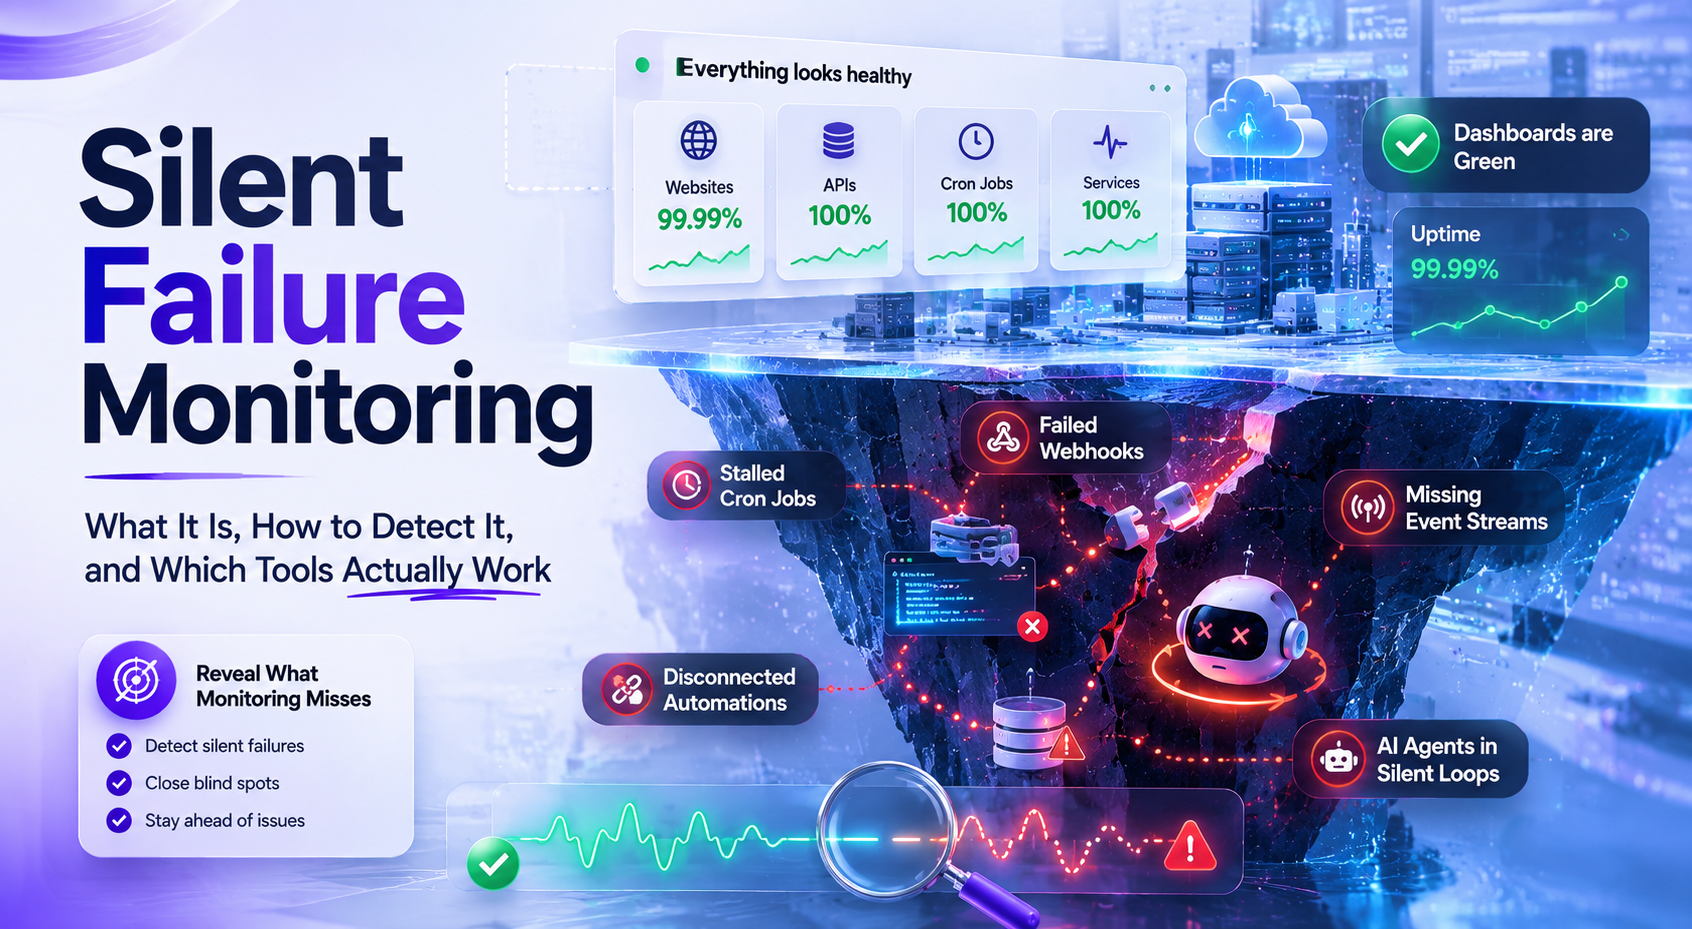
Silent failures don't throw exceptions. They don't create incidents. They just quietly cost you money until someone notices. This is the complete guide to understanding, detecting, and monitoring every type of silent failure in production.
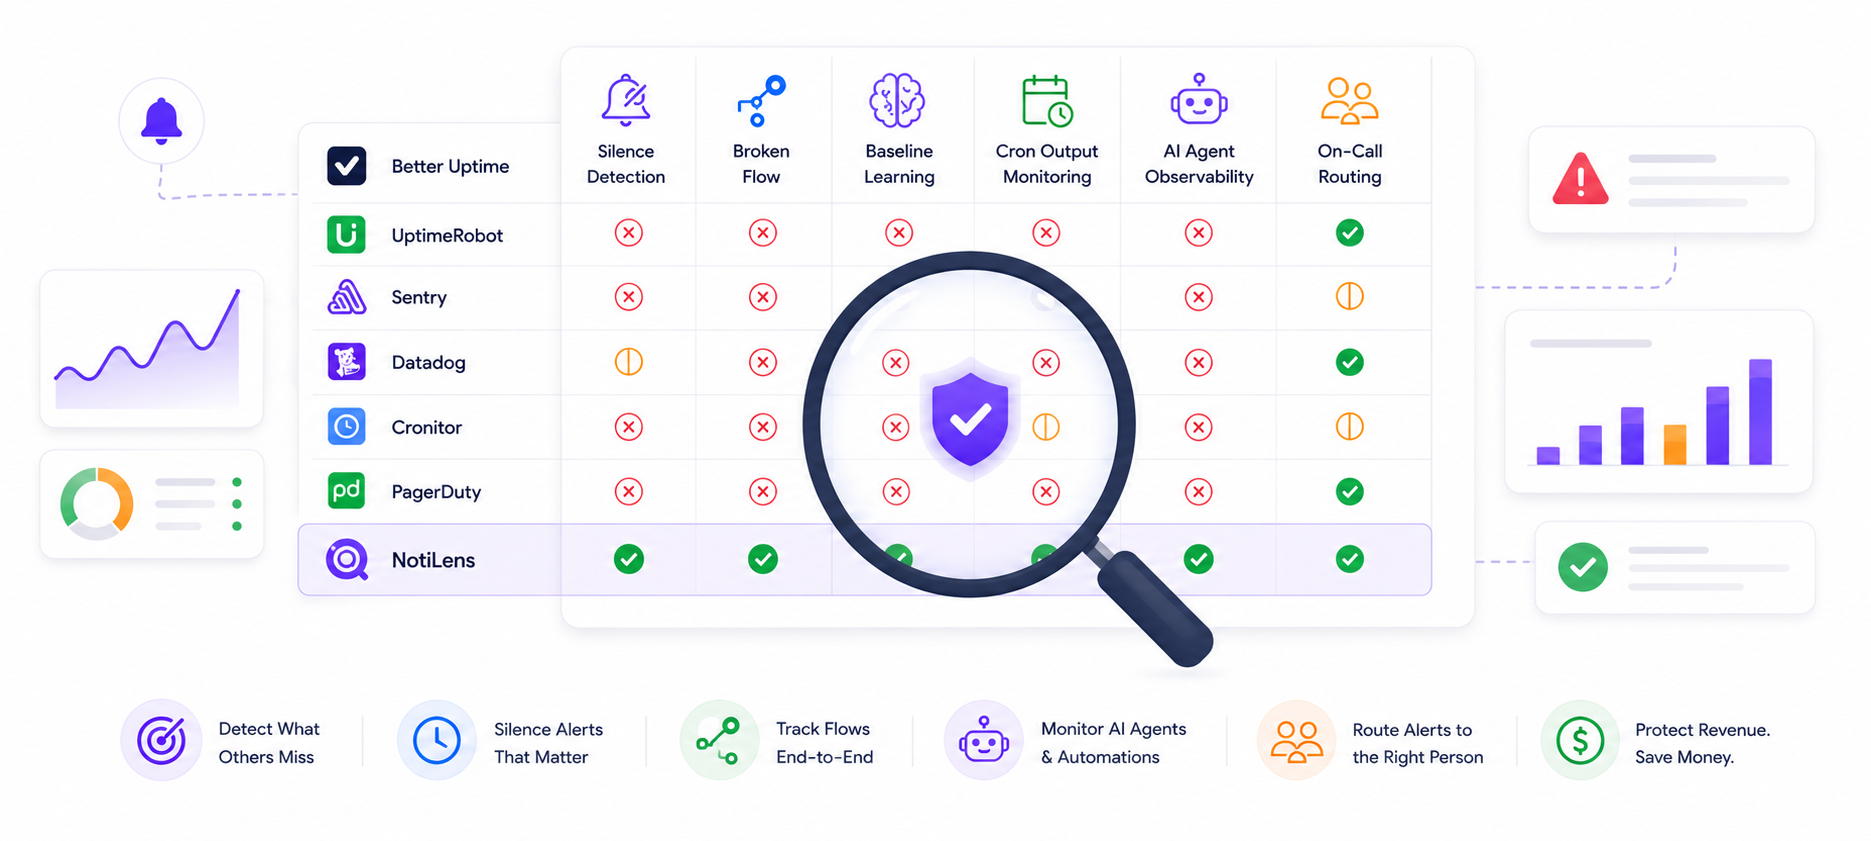
Six monitoring tools compared on the one thing that matters most: do they actually detect silent failures? Heartbeat gaps, broken flows, zero-record cron jobs, AI agent loops — here's what each tool catches and what each misses.
PagerDuty and Incident.io both published comparison posts about each other in 2026. Neither mentioned what small teams and founders actually care about: catching the failures that never create an incident in the first place.
Most comparisons get this wrong from the first sentence. PagerDuty and Incident.io are incident response tools. NotiLens is a business pulse monitor. That distinction matters more than any feature table.
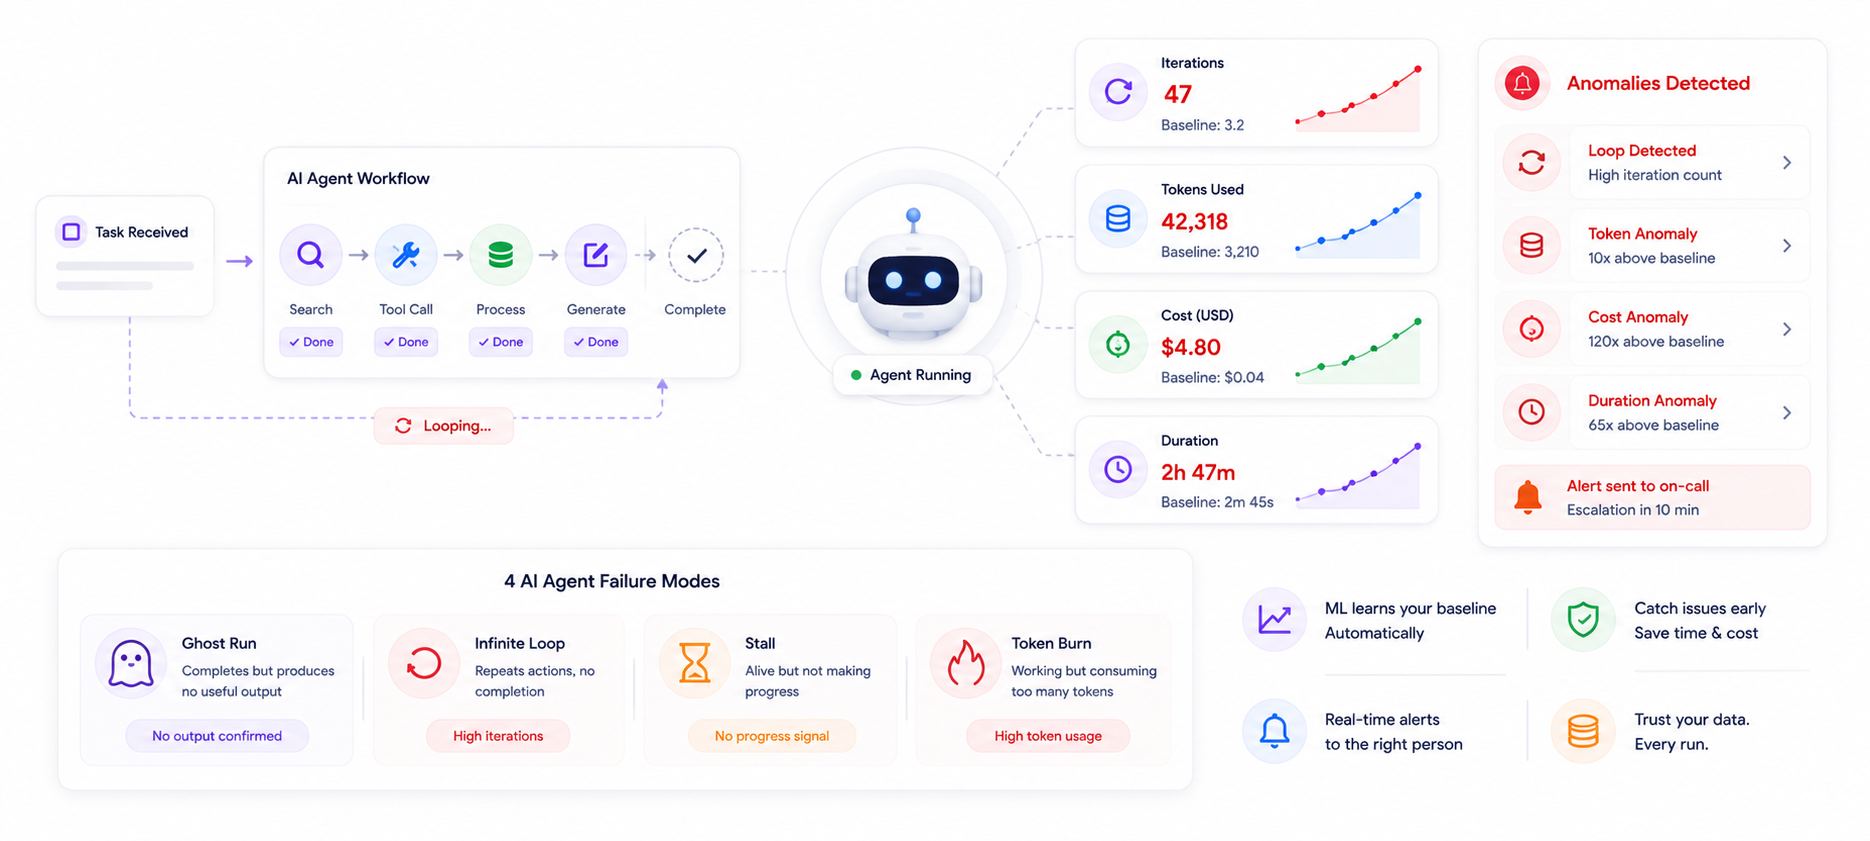
There are two questions you can ask about an AI agent running in production. Is it running? And is it working? Most monitoring stacks answer the first well. None of them answer the second.
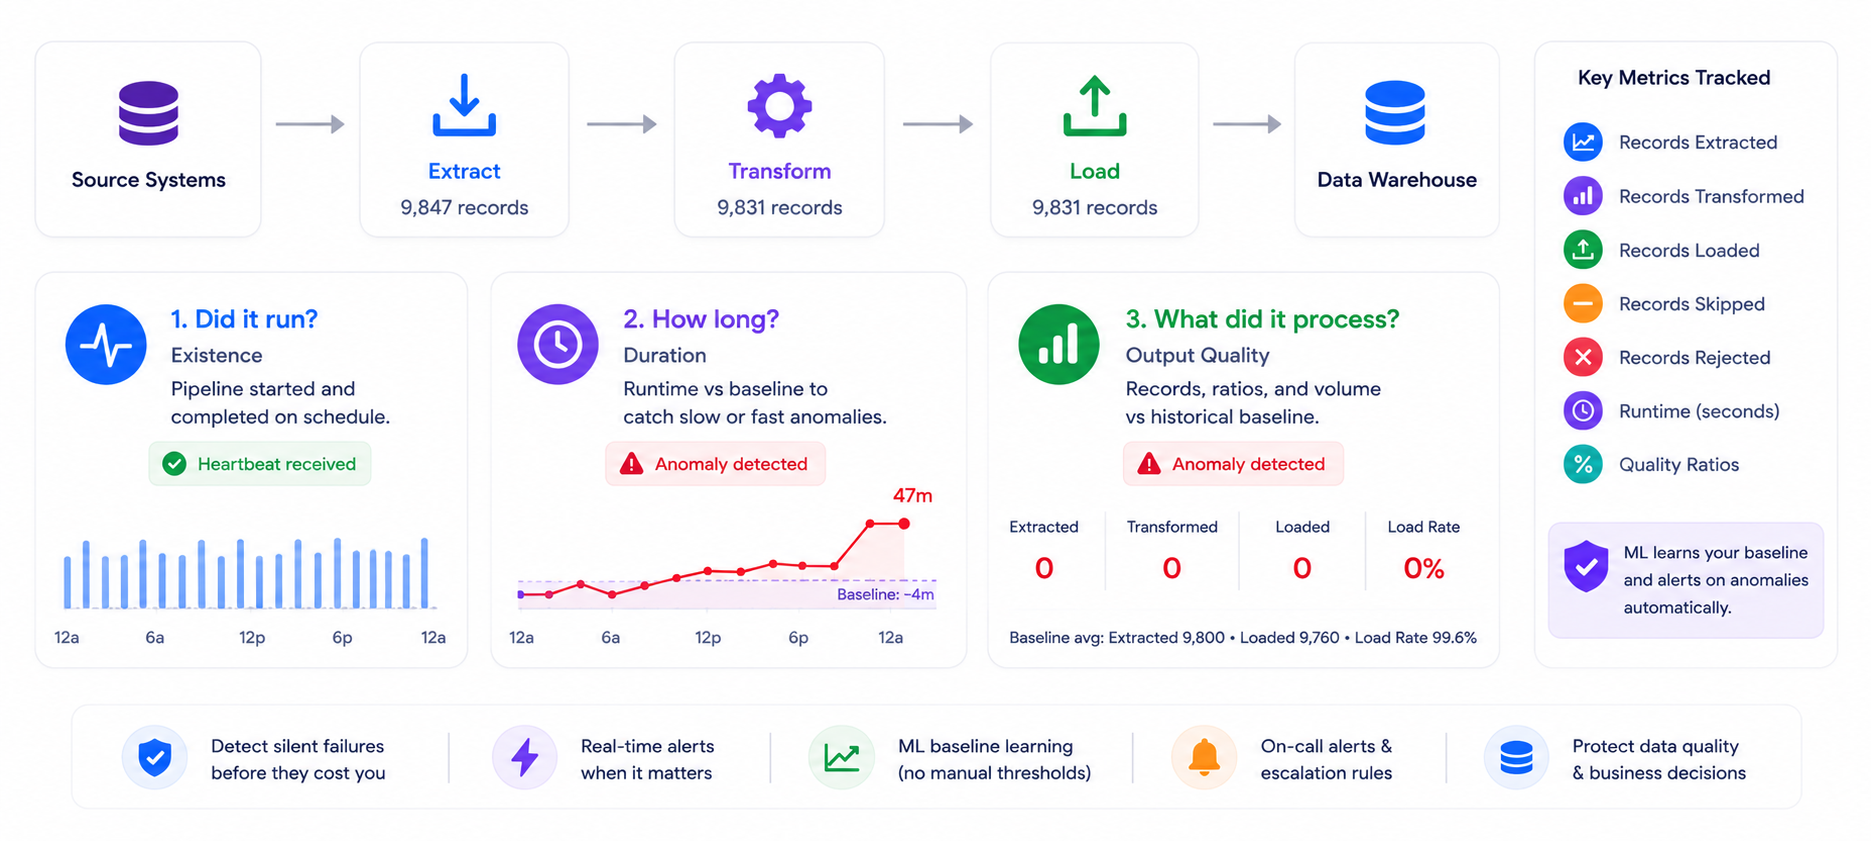
ETL pipelines fail silently more than any other part of a data stack. The job runs. The exit code is 0. Zero records were processed. Your data warehouse is stale and nobody knows. Here's how to catch it.
Not all monitoring tools detect silent failures. Here's how uptime monitors, error trackers, APM tools, and business pulse monitoring compare — and what each one actually catches.
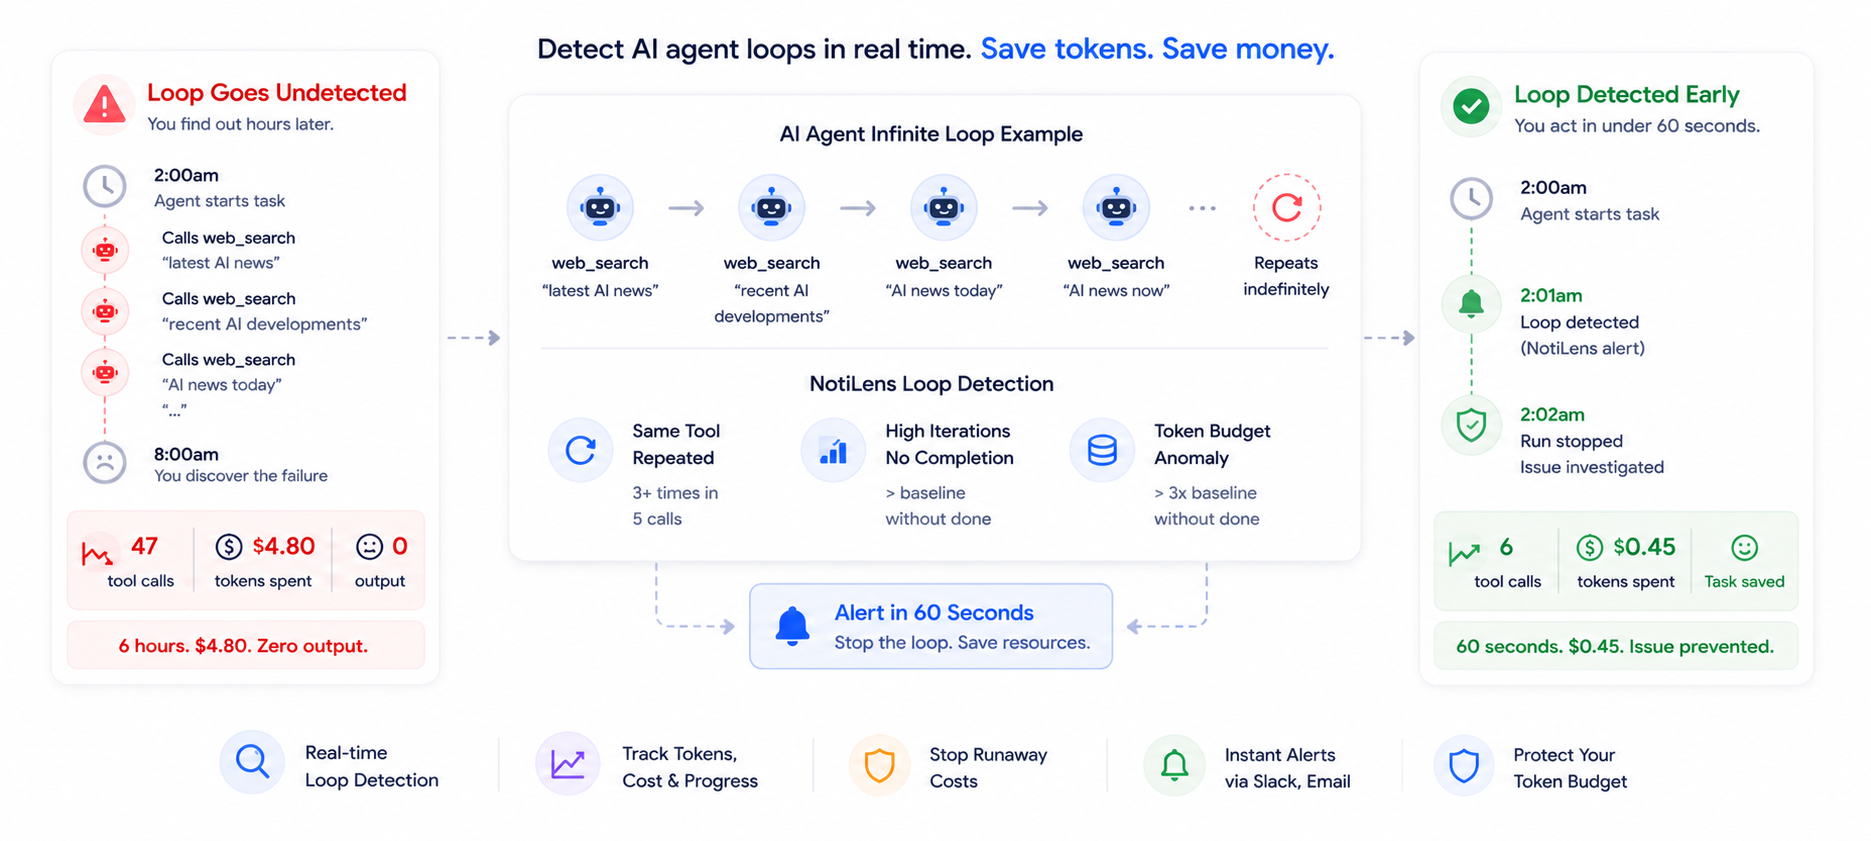
AI agent infinite loops don't throw exceptions. They look like normal activity — tool calls firing, tokens consuming, the process alive — until the budget is gone and the output is empty. Here's how to detect and stop them in real time.
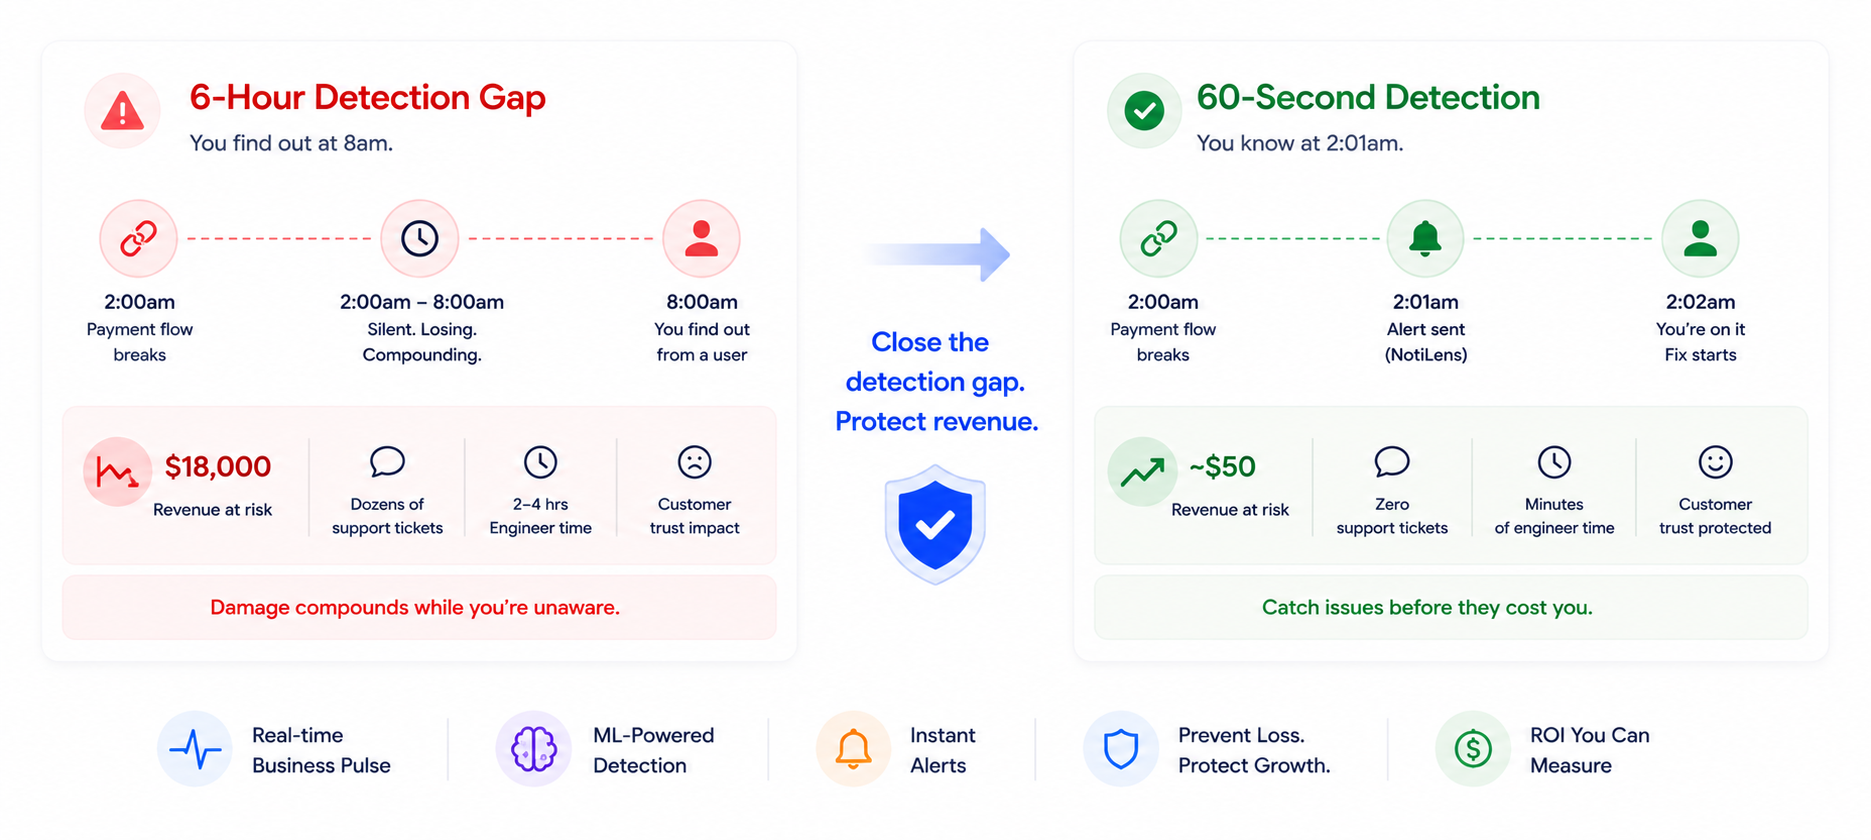
The detection gap is where silent failures compound — and most monitoring stacks have no answer for it. Here's the calculation nobody runs, and why detection time matters more than fix time.
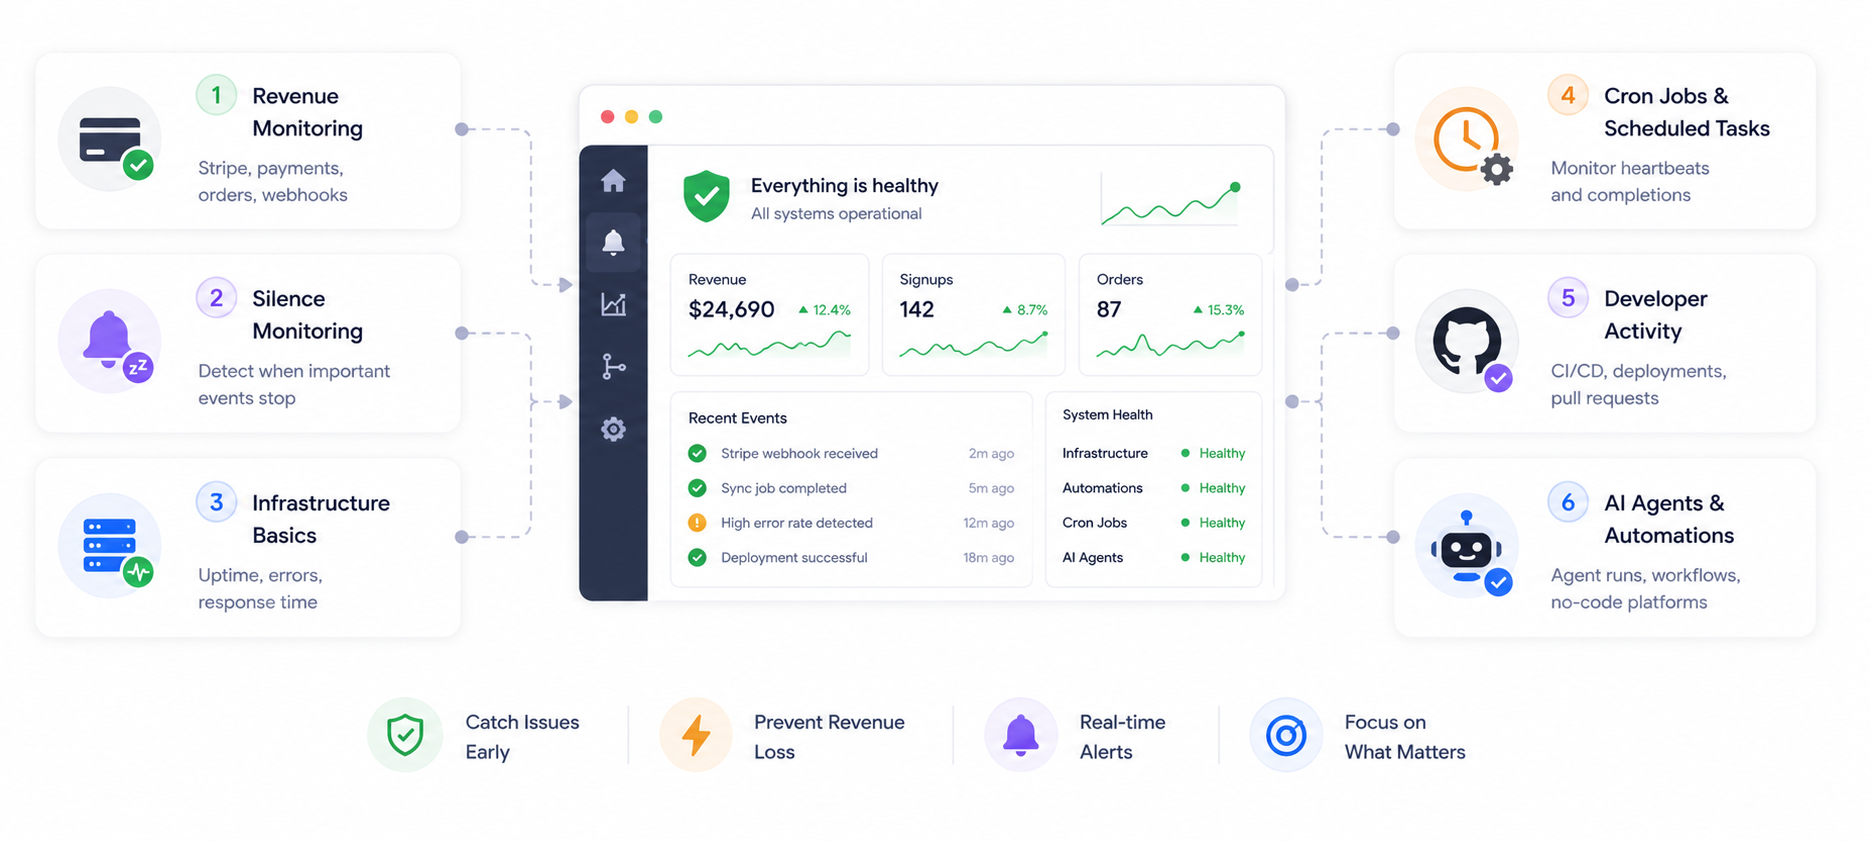
You're a founder. You don't have an SRE on call at 2am. You have a laptop, a Slack, and the vague anxiety that something is quietly breaking right now. Here's the monitoring stack I wish I'd had from day one.
Pushover is a $5 push notification pipe. It's excellent for solo developers. The moment you need silence detection, on-call scheduling, business event monitoring, or team routing — it hits a wall. Here are 7 alternatives that go further.
AI agents fail differently from regular software. They don't crash — they drift, loop, stall, and consume resources while producing nothing. This guide covers the two failure modes unique to agentic AI and how to monitor for both.
Most SaaS founders look at dashboards. The best ones get alerted. Here are the 10 metrics that matter most — and exactly what to alert on so you find out about problems before your users do.
Alert fatigue is when your monitoring alerts so often that you stop trusting them — and start ignoring them. The solution isn't fewer monitors. It's smarter alerting. Here's what that actually means in practice.
Most on-call tools are built for 50-person SRE teams. This guide covers everything a small team of 2–10 needs to set up proper on-call — rotation, escalation policies, DND, holiday overrides, and timezone-aware scheduling — without the enterprise overhead.
PagerDuty starts at $21/user/month and was designed for 50-person SRE teams. If you're a founder or small team who just needs reliable alerting and on-call without the enterprise overhead — here are 7 better options.
Your uptime monitor is green. Your error rate is clean. Your server is responding. And your business has been quietly bleeding for six hours. This is the silent failure problem — and it's more common than anyone admits.
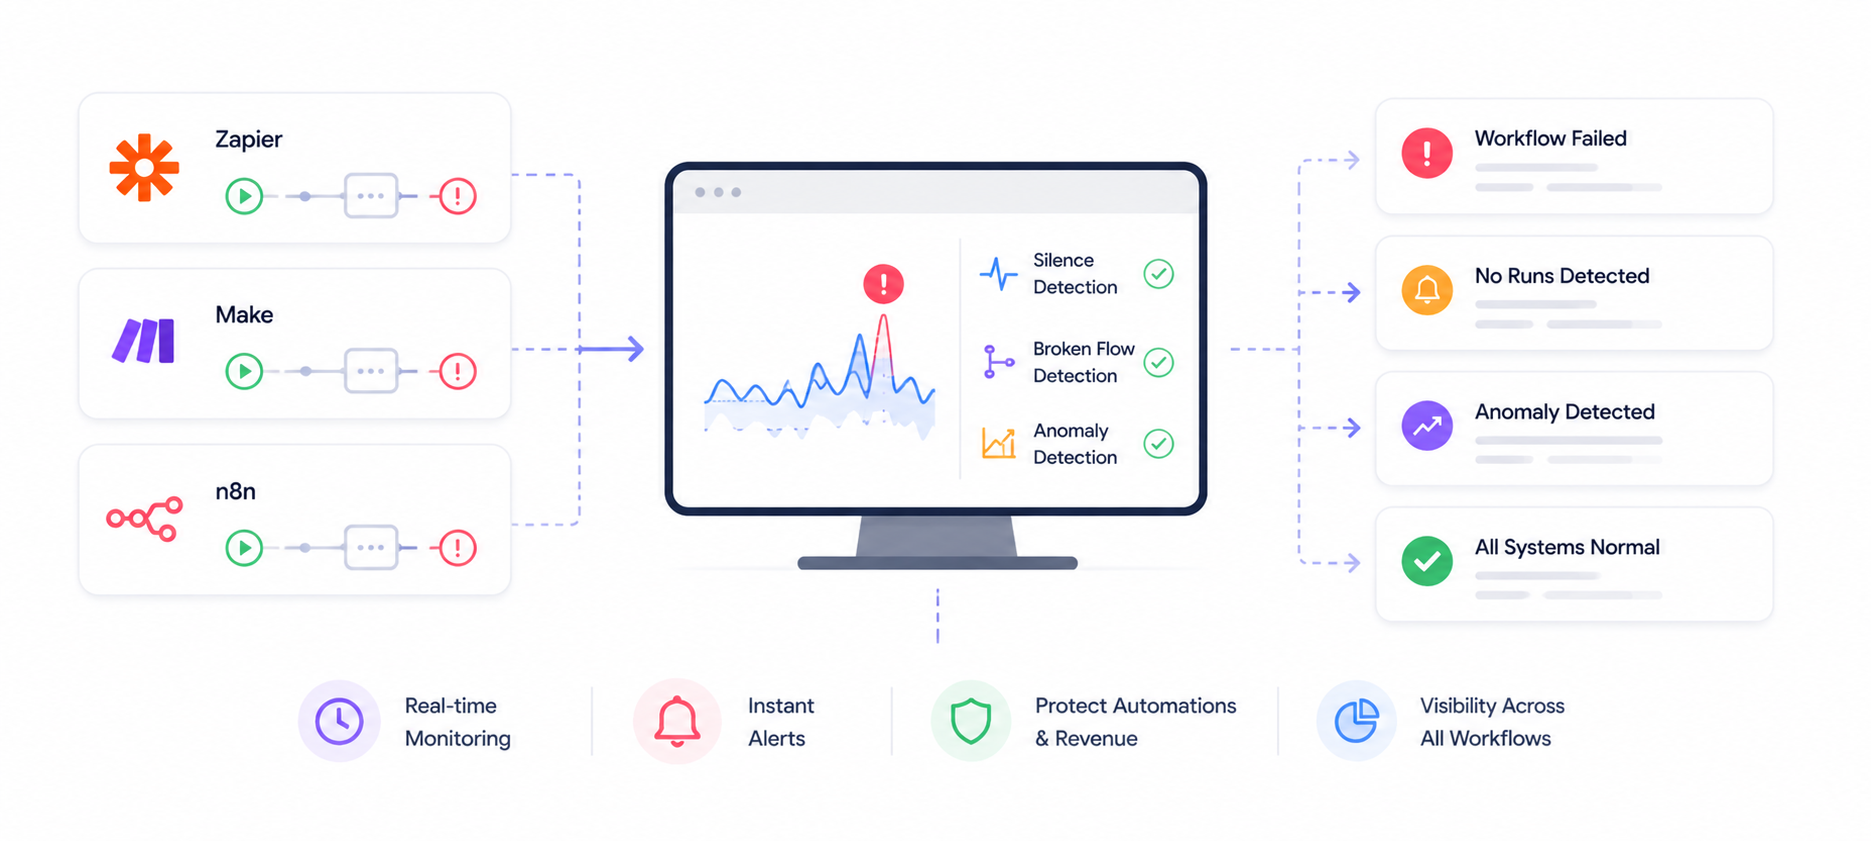
Automation workflows fail silently. A broken Zapier zap, a stalled n8n workflow, or a Make scenario that stopped running three days ago — none of these show up in your uptime monitor. Here's how to catch them.
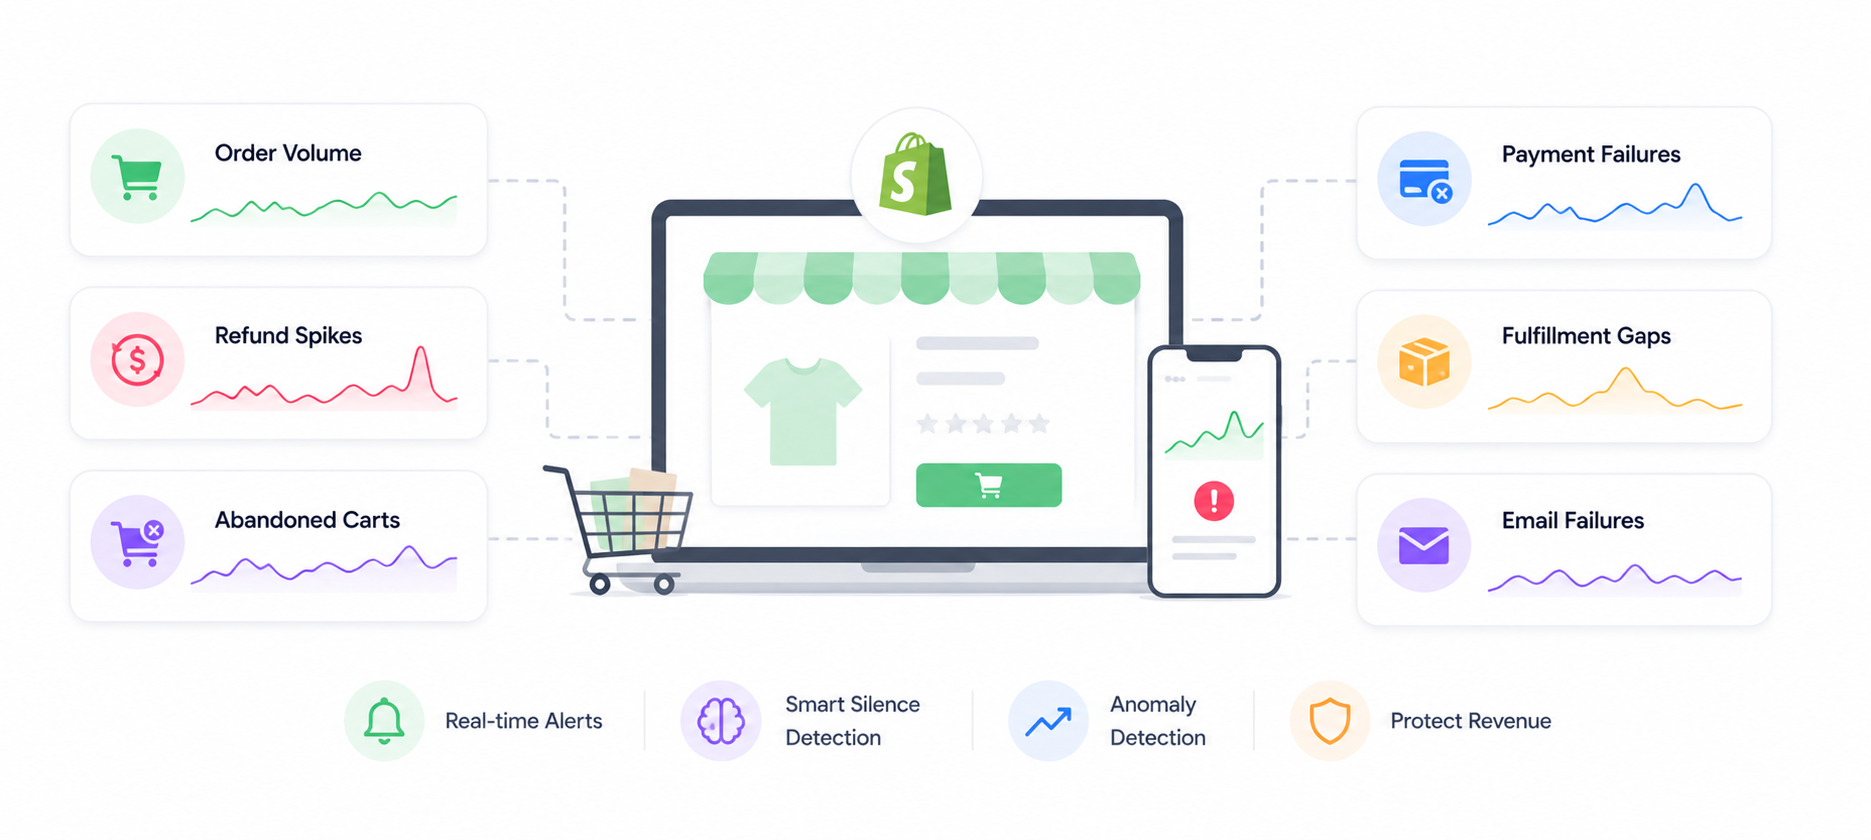
Your Shopify store can be losing revenue right now and your dashboard will show green. This guide covers what to monitor, what to alert on, and how to catch the silent failures that cost e-commerce stores the most money.
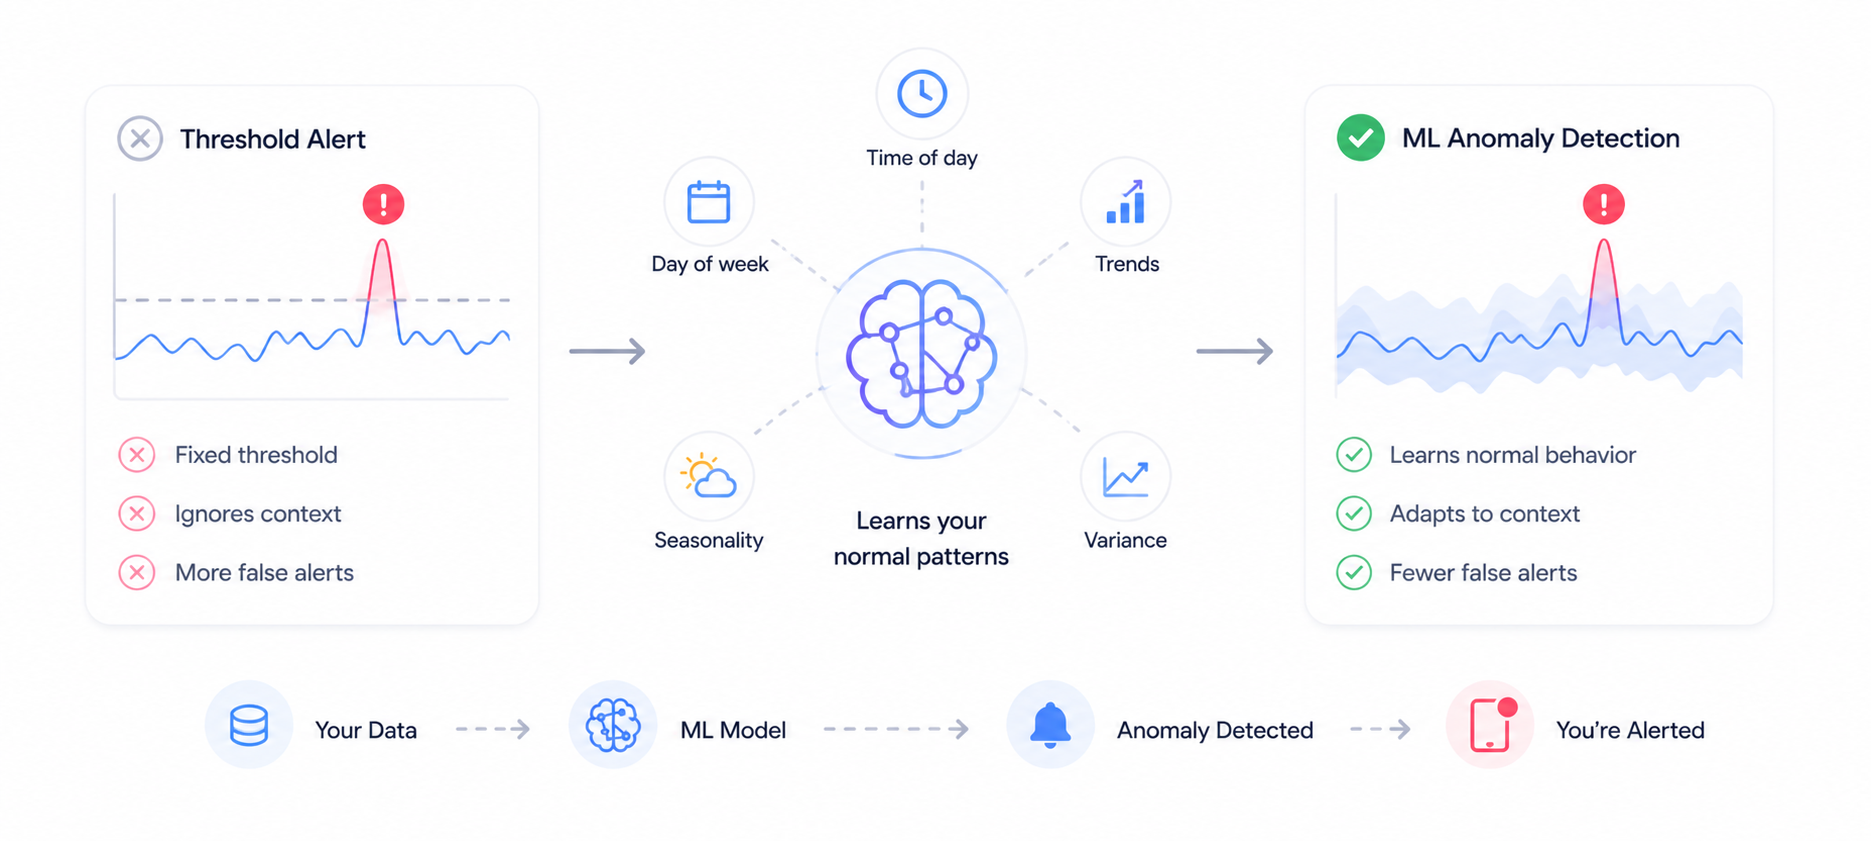
ML anomaly detection watches your business metrics and alerts you when something is genuinely abnormal — without you having to define what 'normal' looks like. Here's how it works, why it matters, and how it's different from threshold alerts.
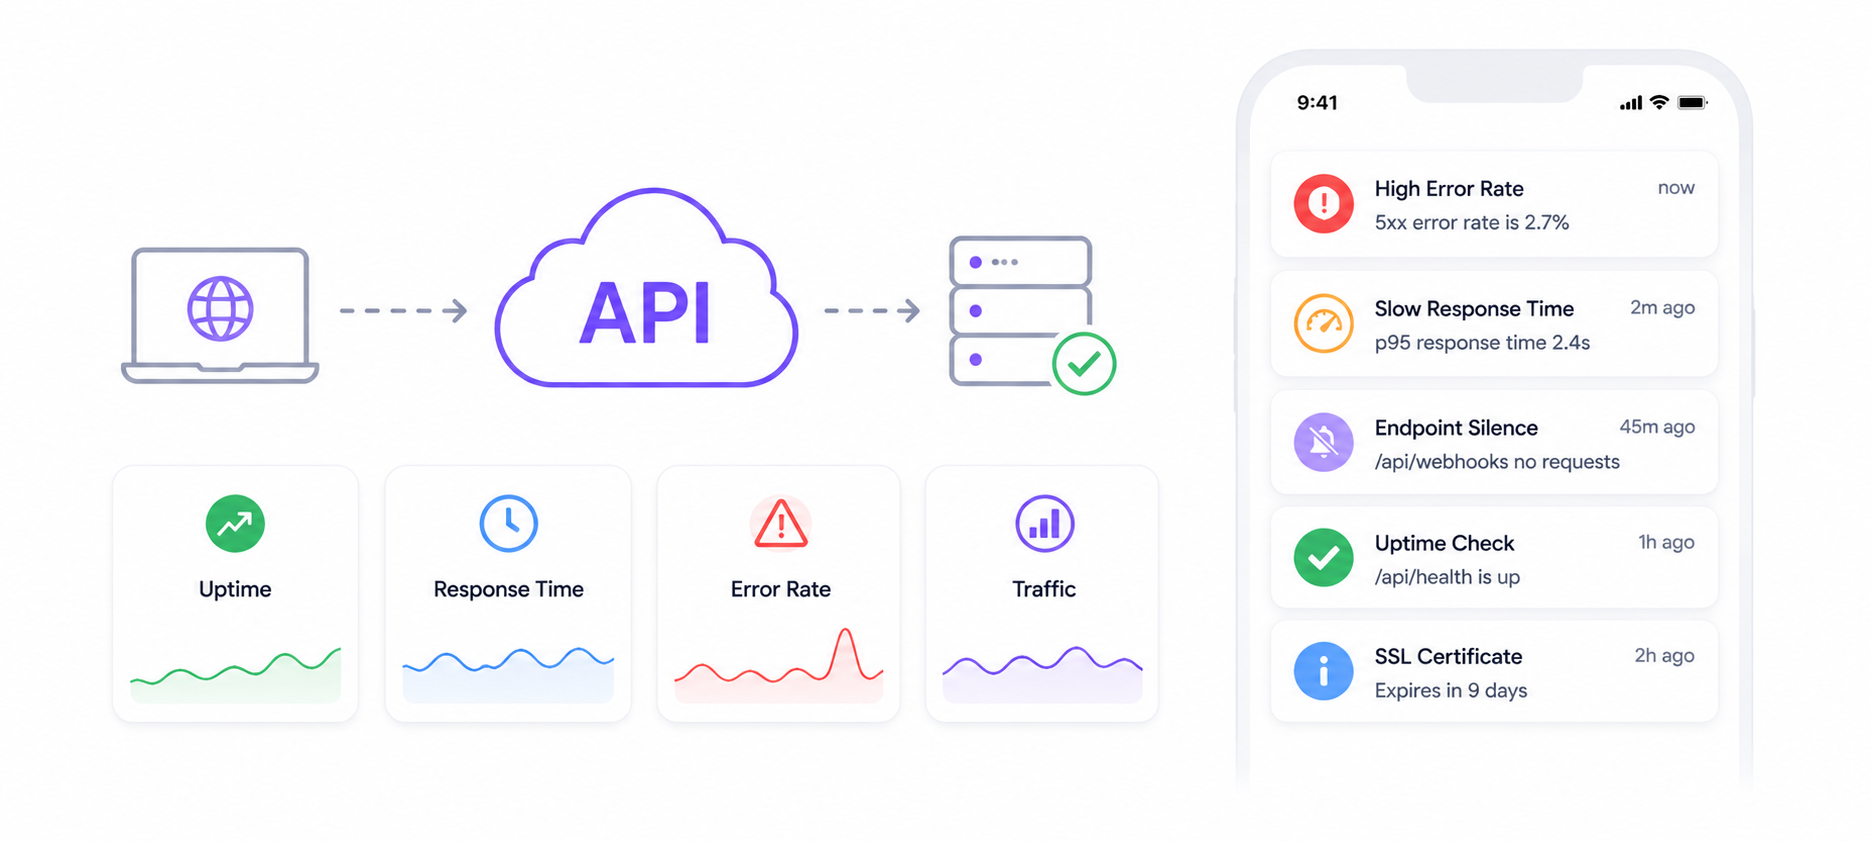
Most teams monitor if their API is up. Few monitor if it's actually healthy. This guide covers the full picture — response time degradation, error rate spikes, silent endpoint failures, and how to alert on all of it.
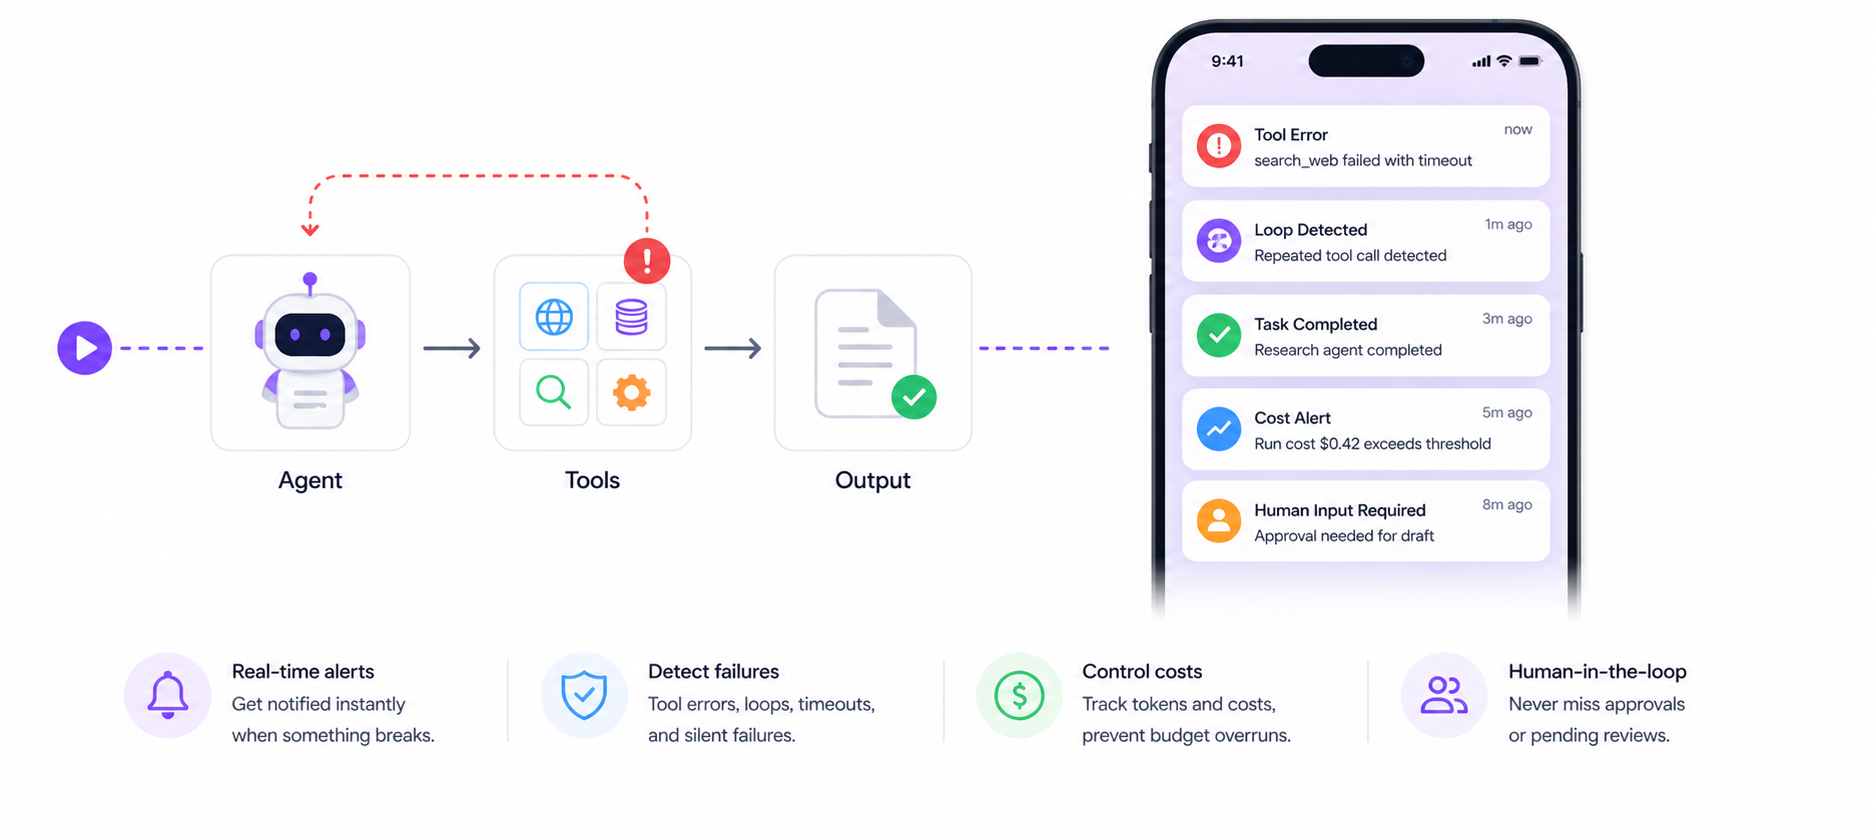
LangChain agents fail silently in production — tool errors, infinite loops, stalled chains, cost spikes. Here's how to add real-time monitoring and alerts to any LangChain agent in under 10 minutes.
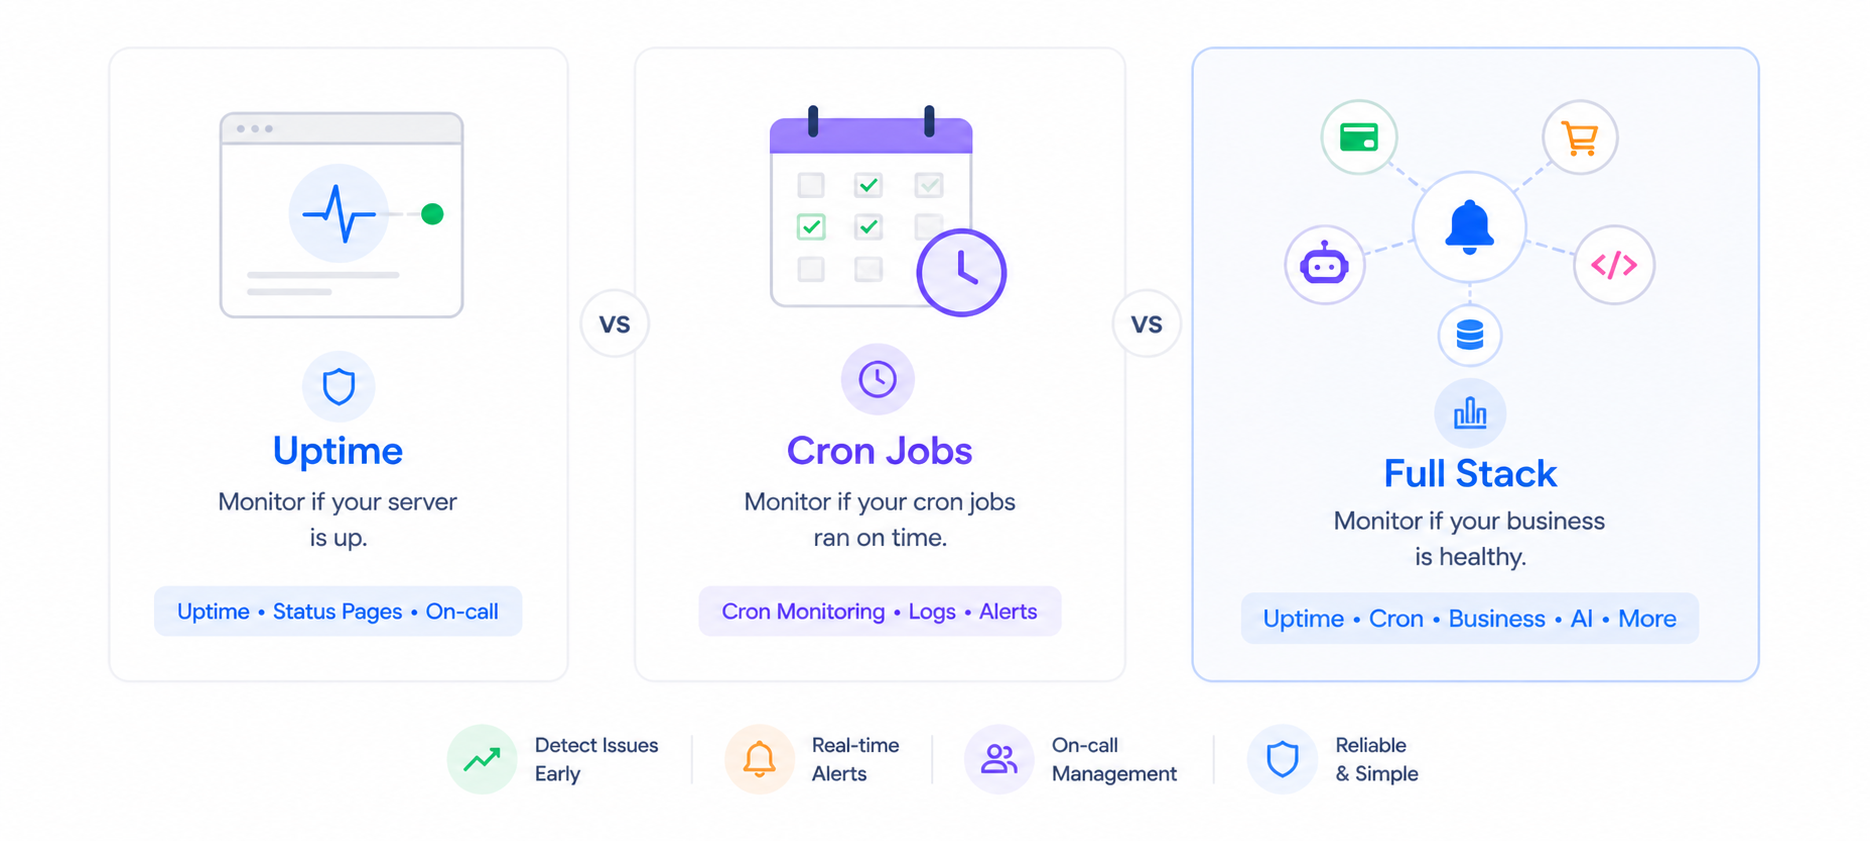
Better Uptime monitors if your server is up. Cronitor monitors if your cron jobs ran. NotiLens monitors whether your business is healthy — payments, orders, agents, jobs, and servers, all in one place with ML-powered silence detection.
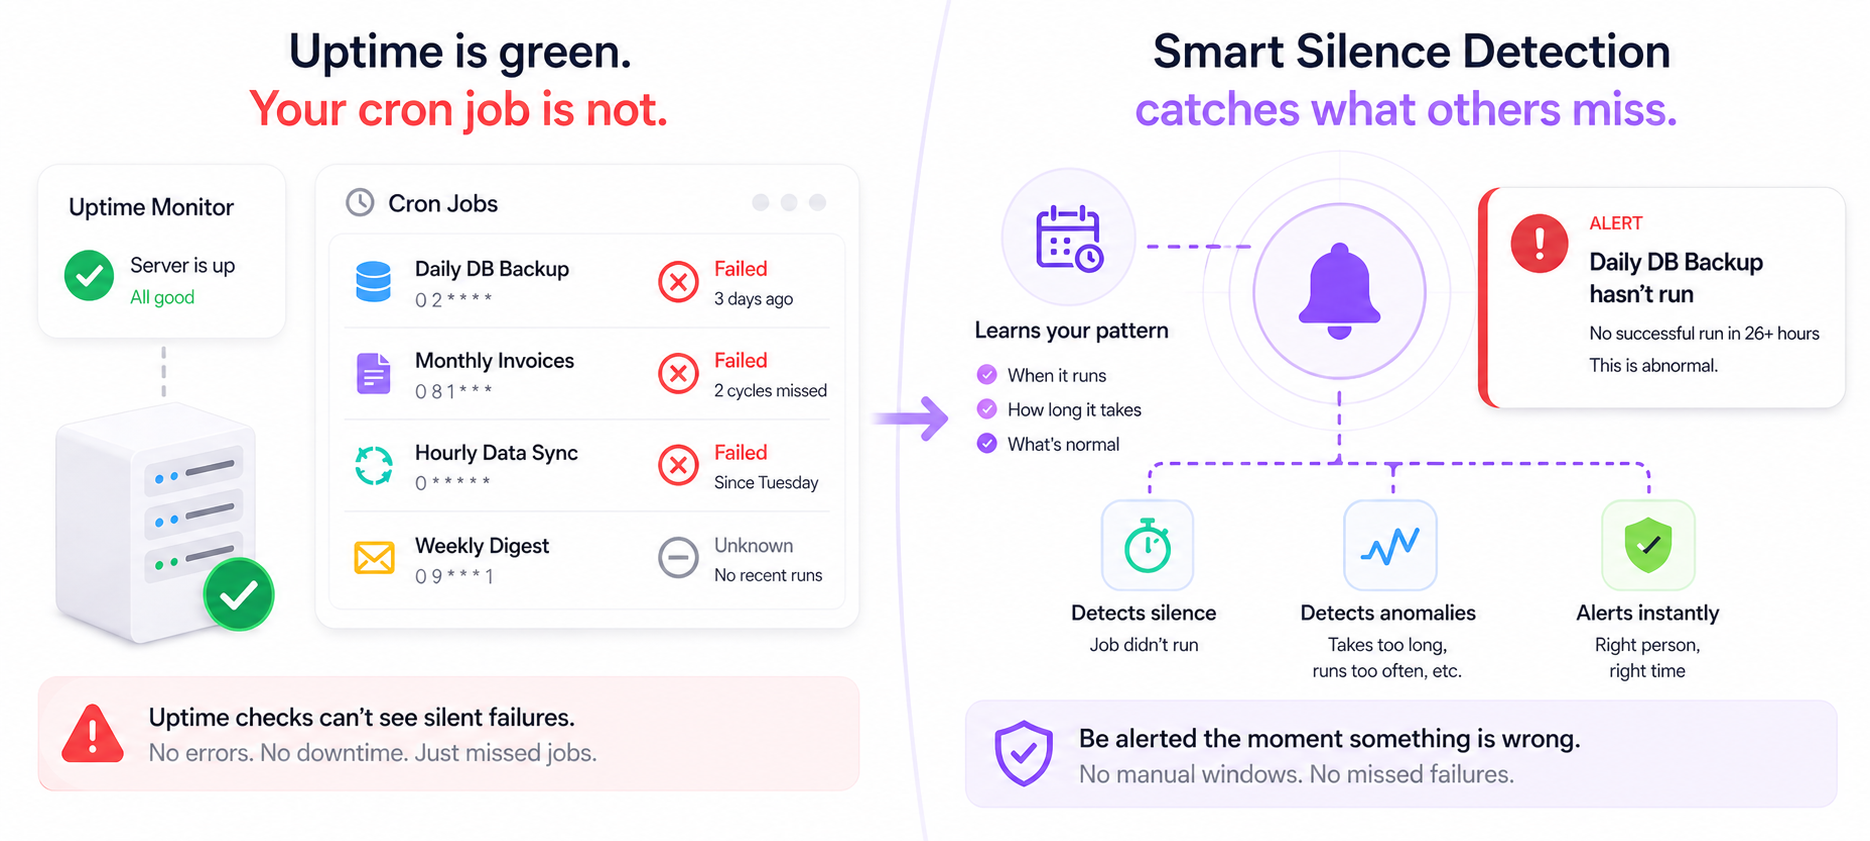
Your server is up. Your uptime monitor is green. But your cron job silently stopped running 3 days ago — and nobody told you. Here's why uptime checks miss this entirely, and what actually works.
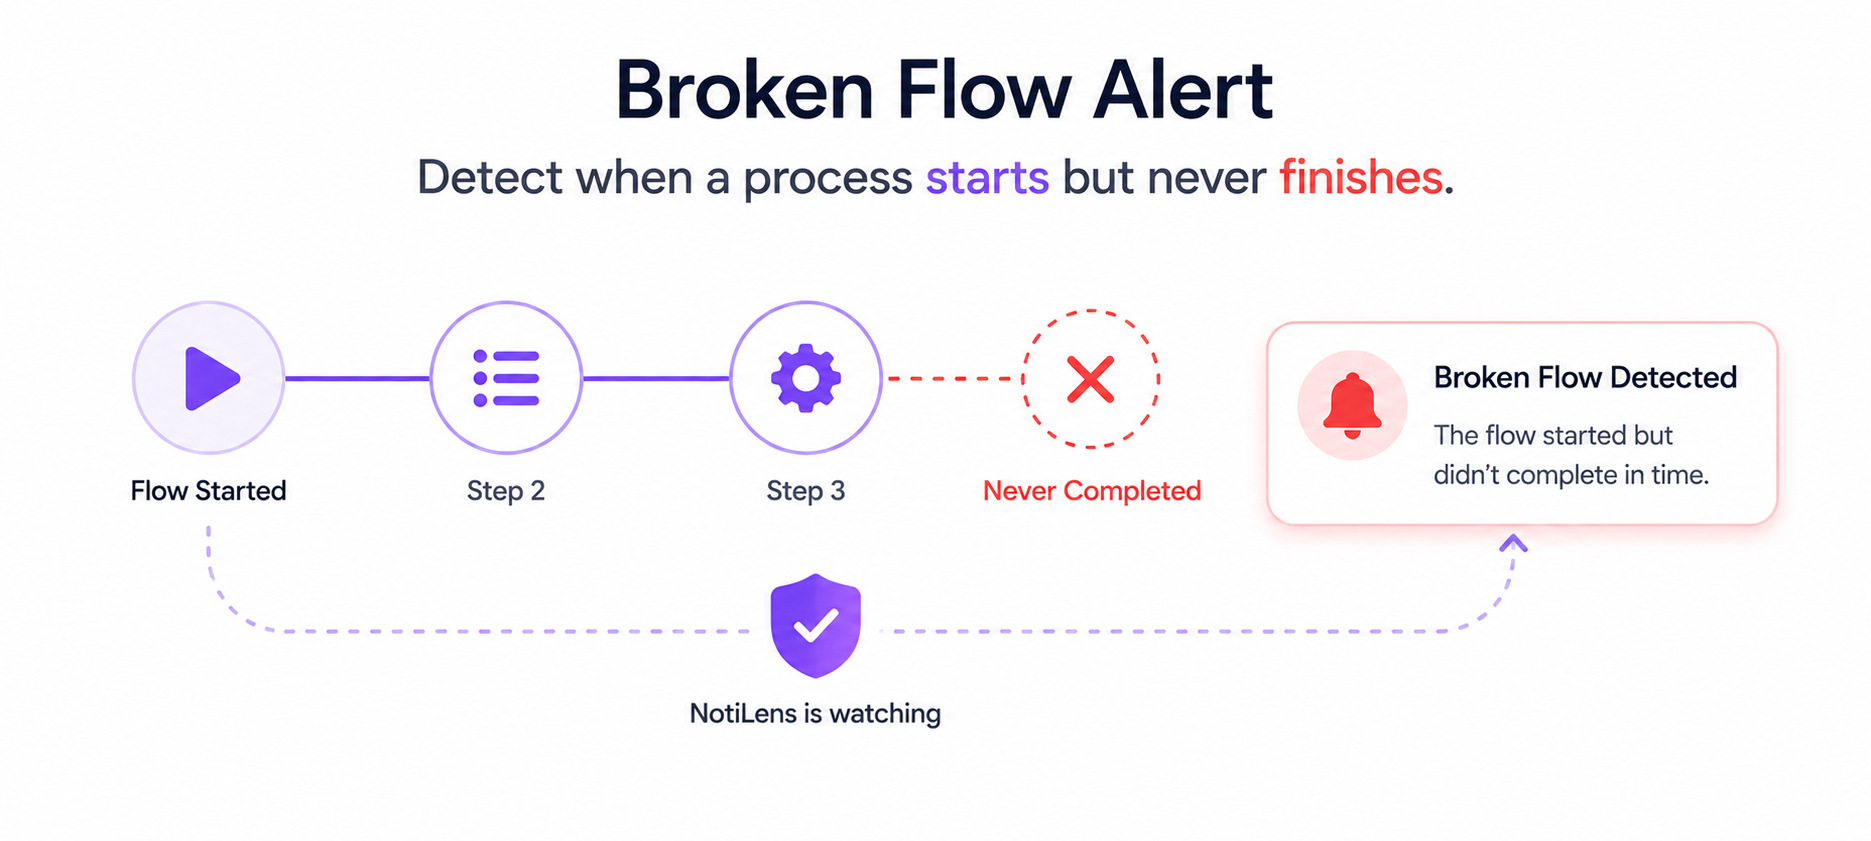
A broken flow alert fires when a multi-step process starts but never finishes. Payment initiated, never completed. Signup started, never confirmed. Job started, never done. Here's how it works and why it matters.
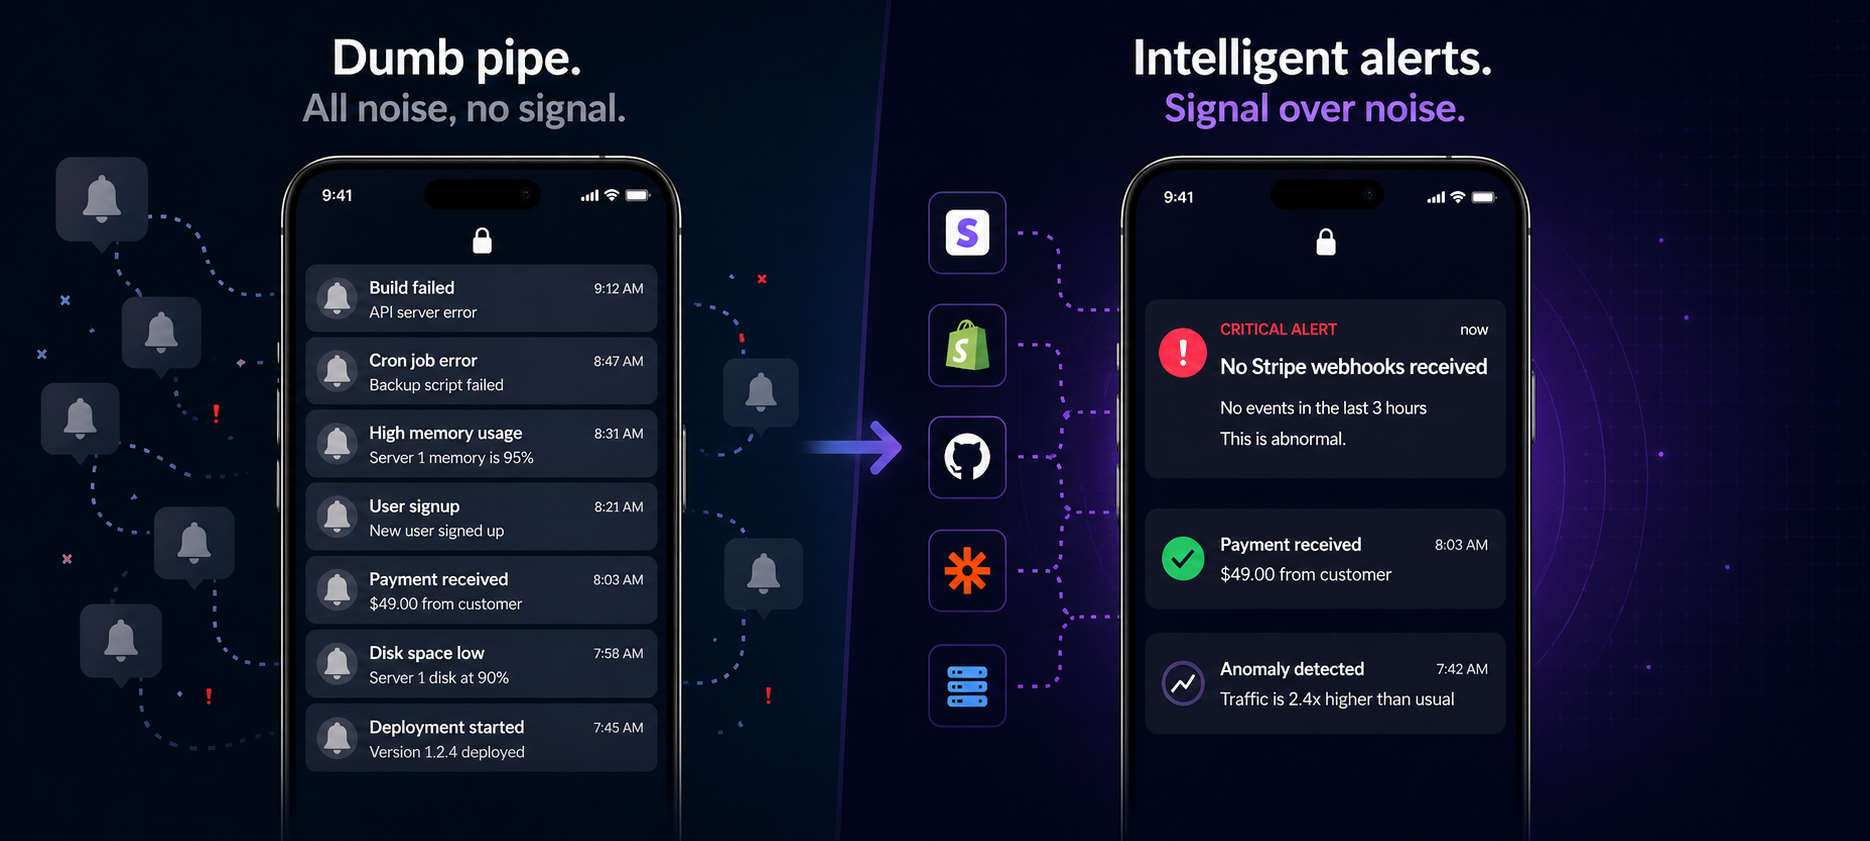
Pushover is a great dumb pipe for push notifications. But when your business needs intelligent alerting — silence detection, on-call scheduling, and ML-powered anomaly detection — it hits a wall fast.
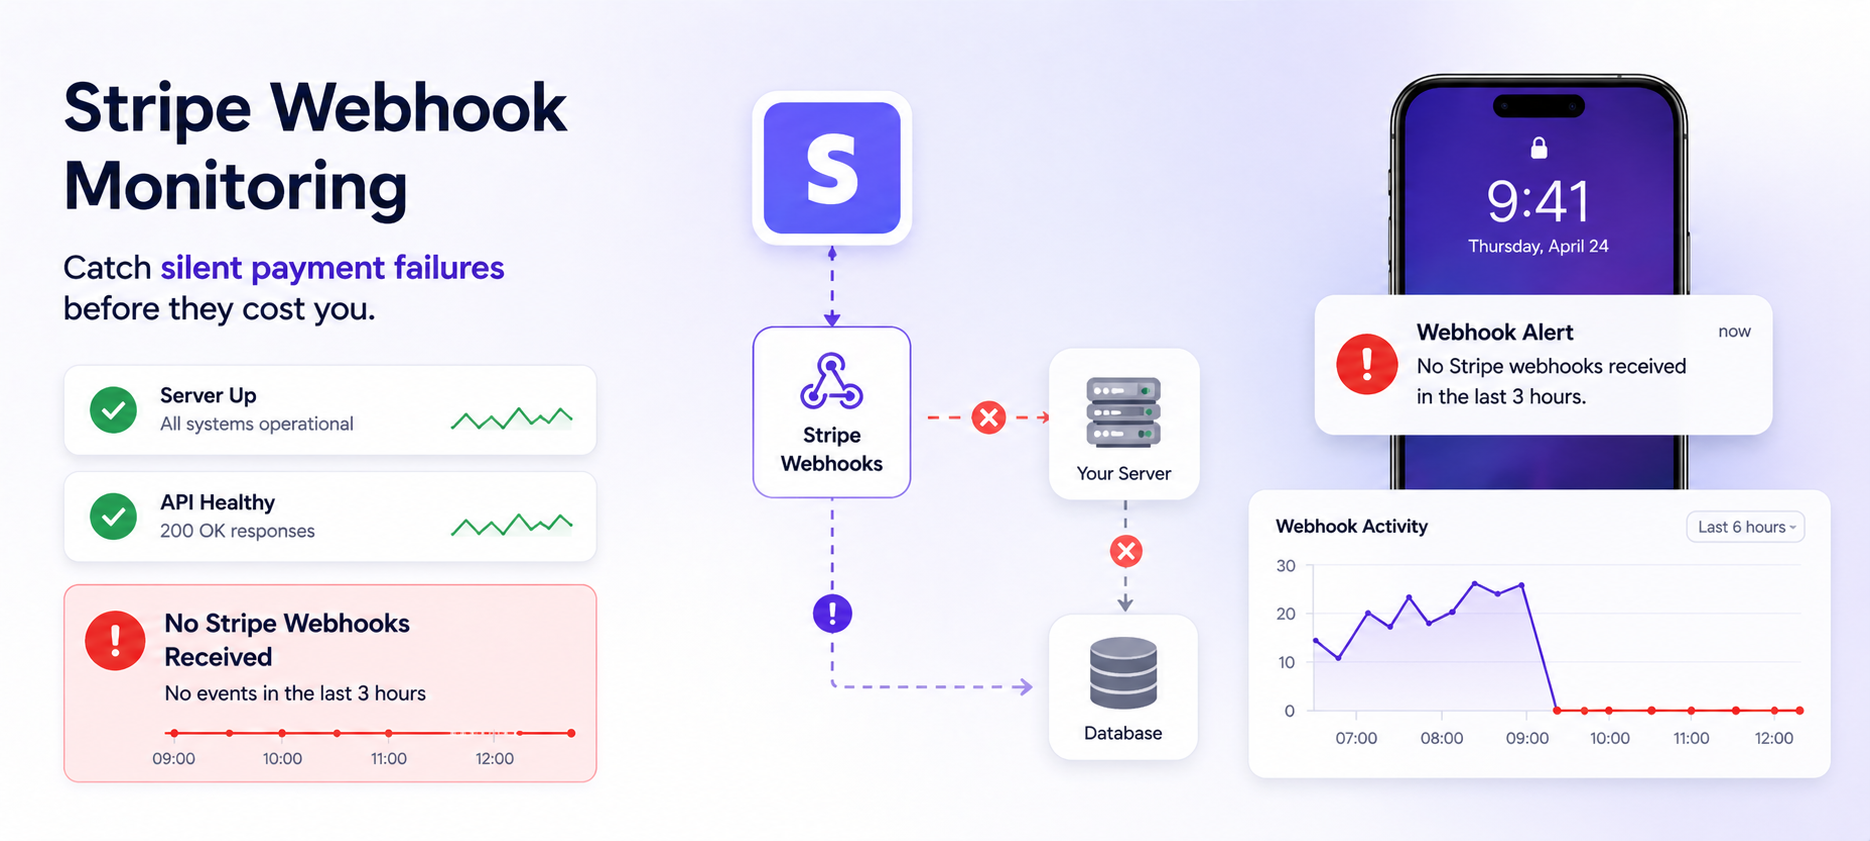
Stripe webhooks fail silently. Your server looks fine, your API is up, but payments are being processed with no record in your database. Here's how to catch it before it costs you.
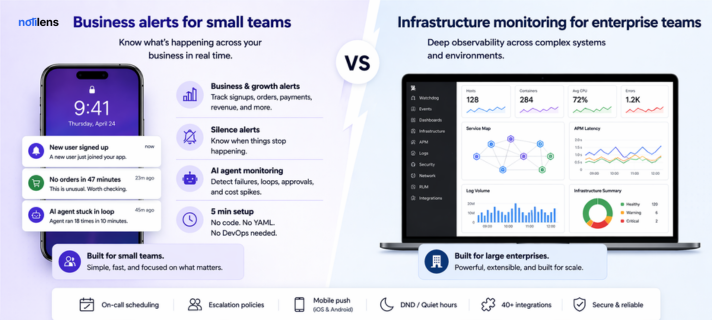
Datadog is a powerful infrastructure observability platform — but it costs $100+/month before you've monitored a single Stripe payment. Here's how NotiLens compares for founders and small teams.
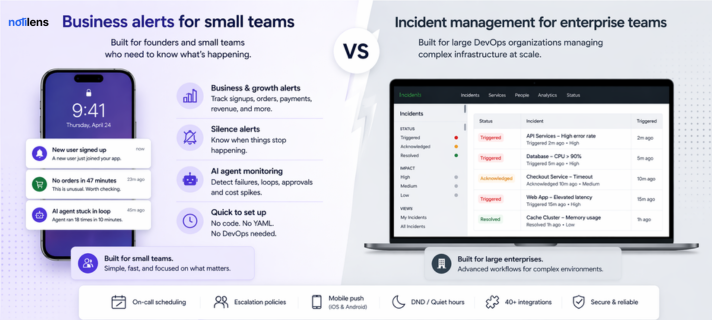
PagerDuty is built for enterprise DevOps. NotiLens is built for founders and small teams who need business-level alerts without a 6-week onboarding. Here's how they compare.
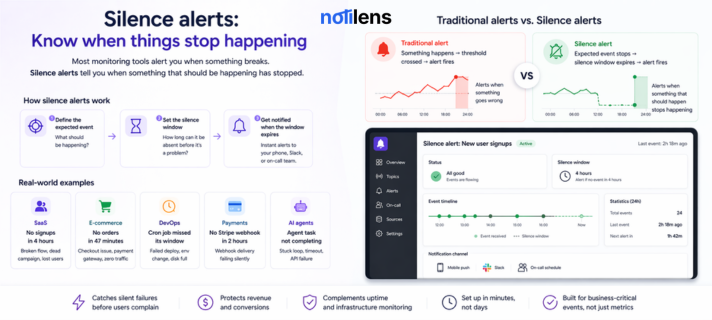
Most monitoring tools alert you when something breaks. Silence alerts tell you when something that should be happening has stopped — and that's often the more expensive failure.
India's creative collaboration marketplace replaced manual dashboard-watching with real-time alerts across signups, server health, AI costs, and user activity.