Alert fatigue is when your monitoring alerts so often that you stop trusting them — and start ignoring them. The solution isn't fewer monitors. It's smarter alerting. Here's what that actually means in practice.
Most on-call tools are built for 50-person SRE teams. This guide covers everything a small team of 2–10 needs to set up proper on-call — rotation, escalation policies, DND, holiday overrides, and timezone-aware scheduling — without the enterprise overhead.
Your uptime monitor is green. Your error rate is clean. Your server is responding. And your business has been quietly bleeding for six hours. This is the silent failure problem — and it's more common than anyone admits.
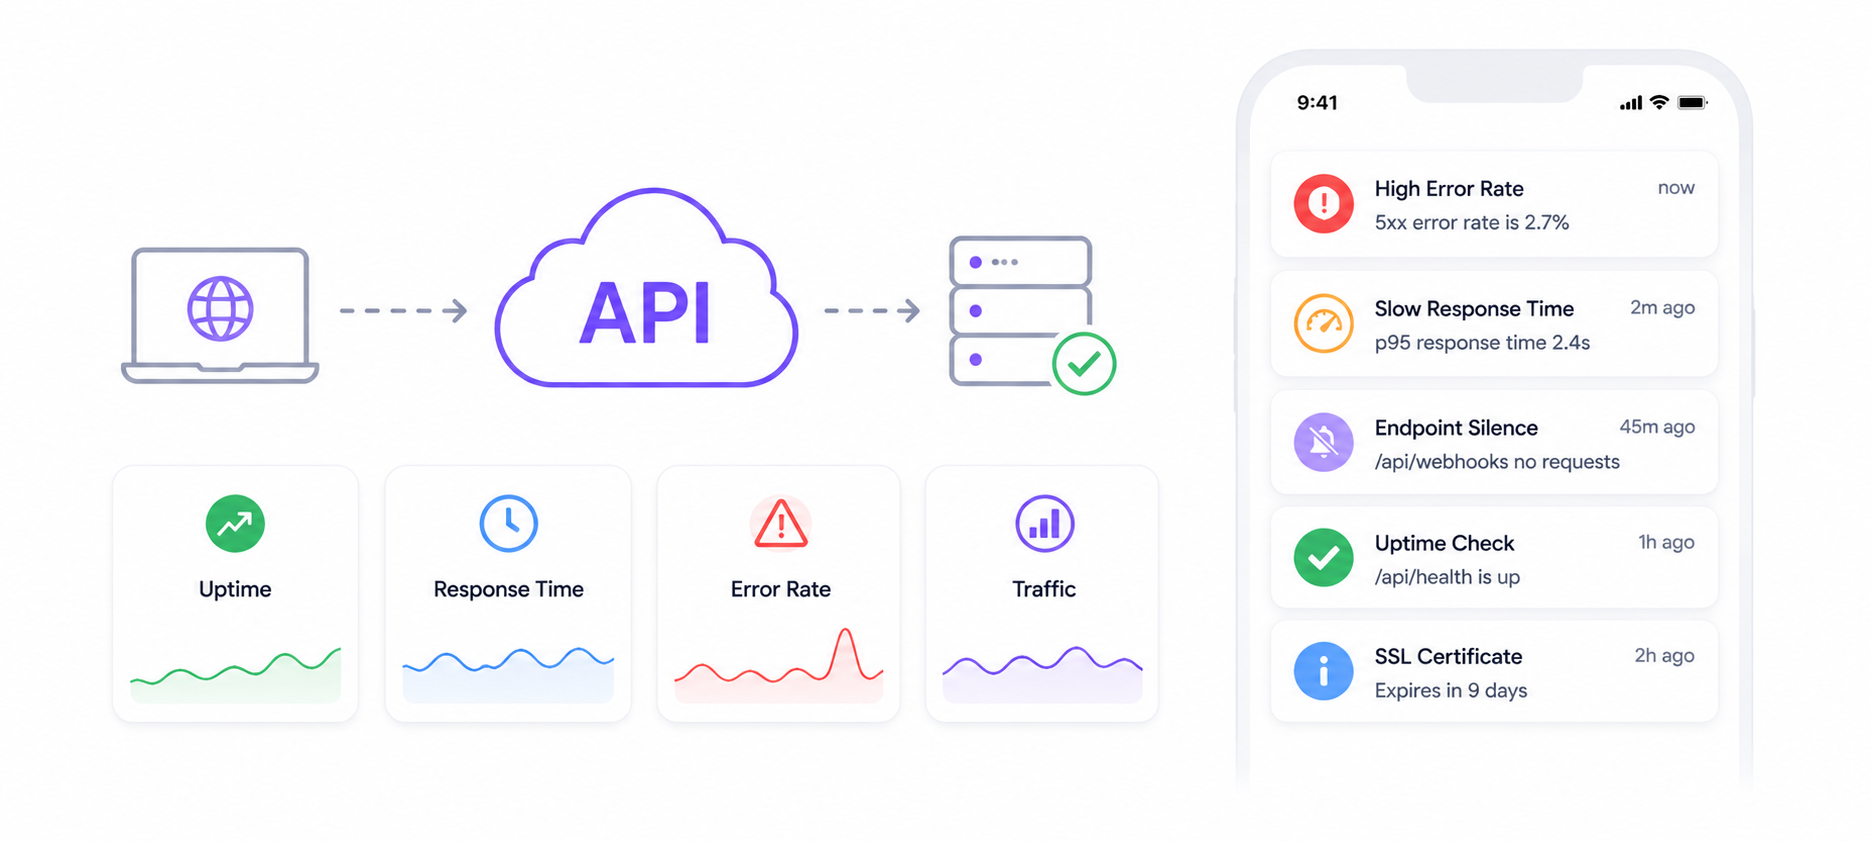
Most teams monitor if their API is up. Few monitor if it's actually healthy. This guide covers the full picture — response time degradation, error rate spikes, silent endpoint failures, and how to alert on all of it.
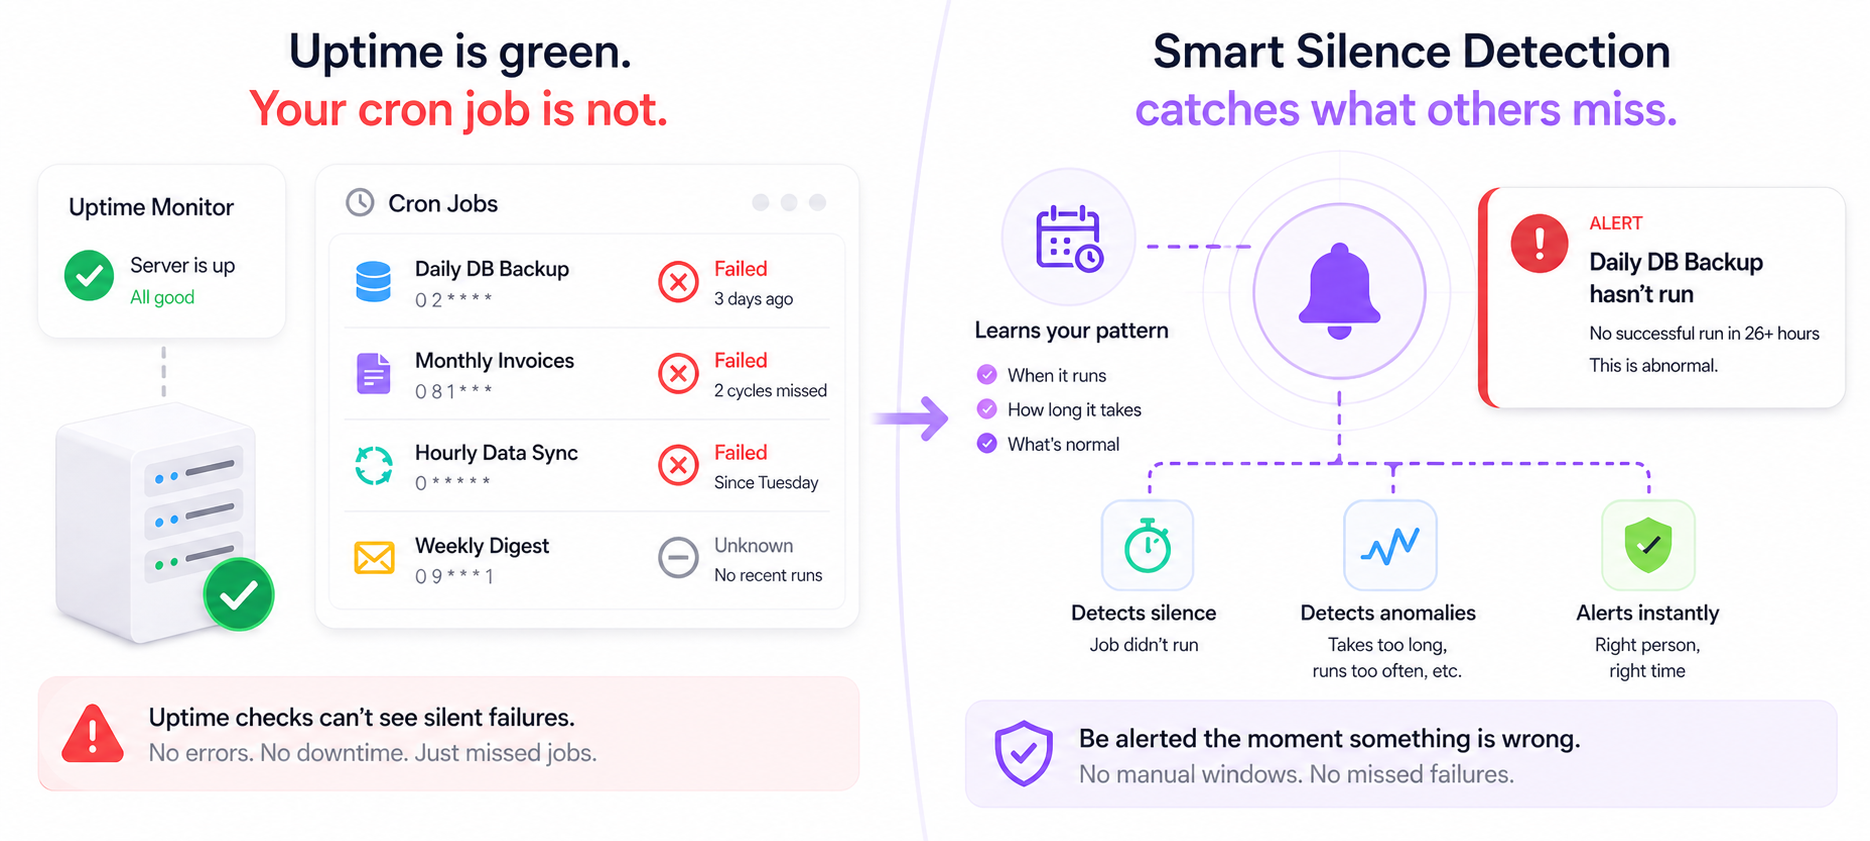
Your server is up. Your uptime monitor is green. But your cron job silently stopped running 3 days ago — and nobody told you. Here's why uptime checks miss this entirely, and what actually works.
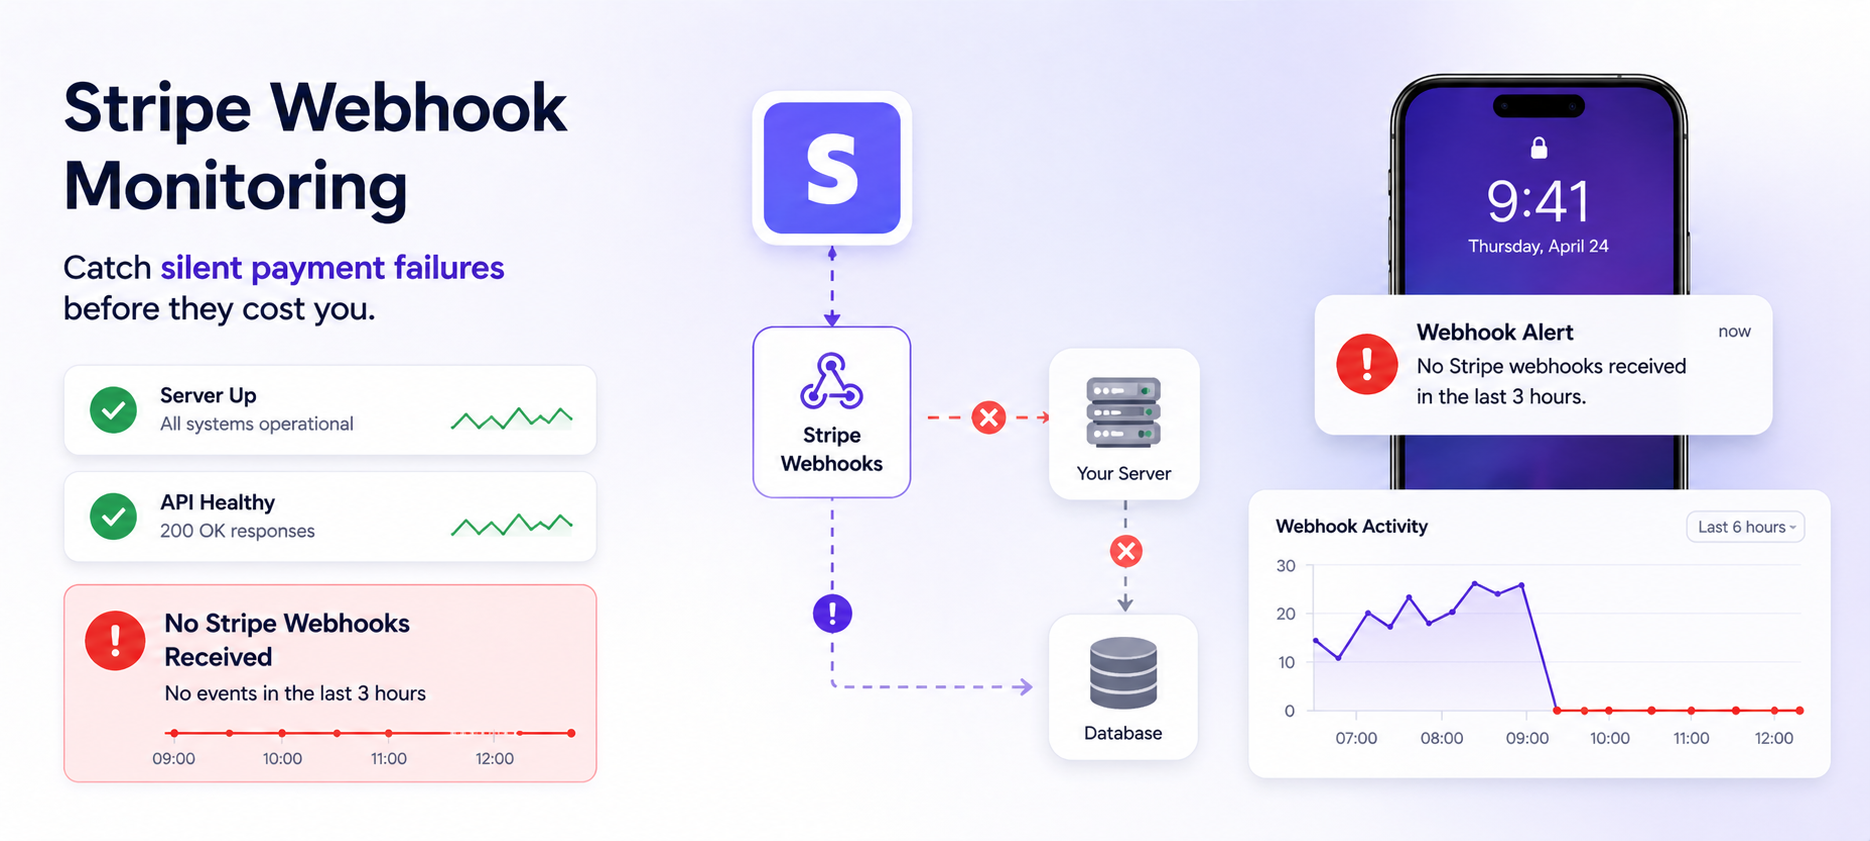
Stripe webhooks fail silently. Your server looks fine, your API is up, but payments are being processed with no record in your database. Here's how to catch it before it costs you.
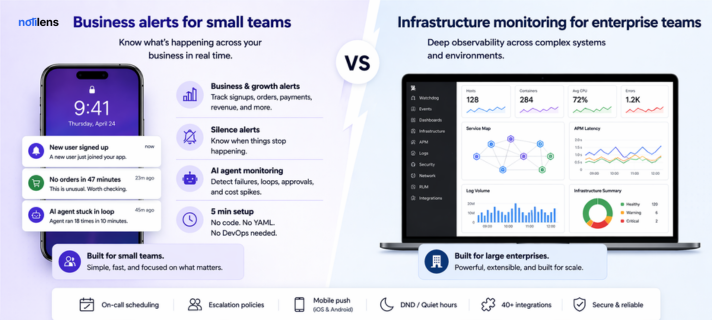
Datadog is a powerful infrastructure observability platform — but it costs $100+/month before you've monitored a single Stripe payment. Here's how NotiLens compares for founders and small teams.