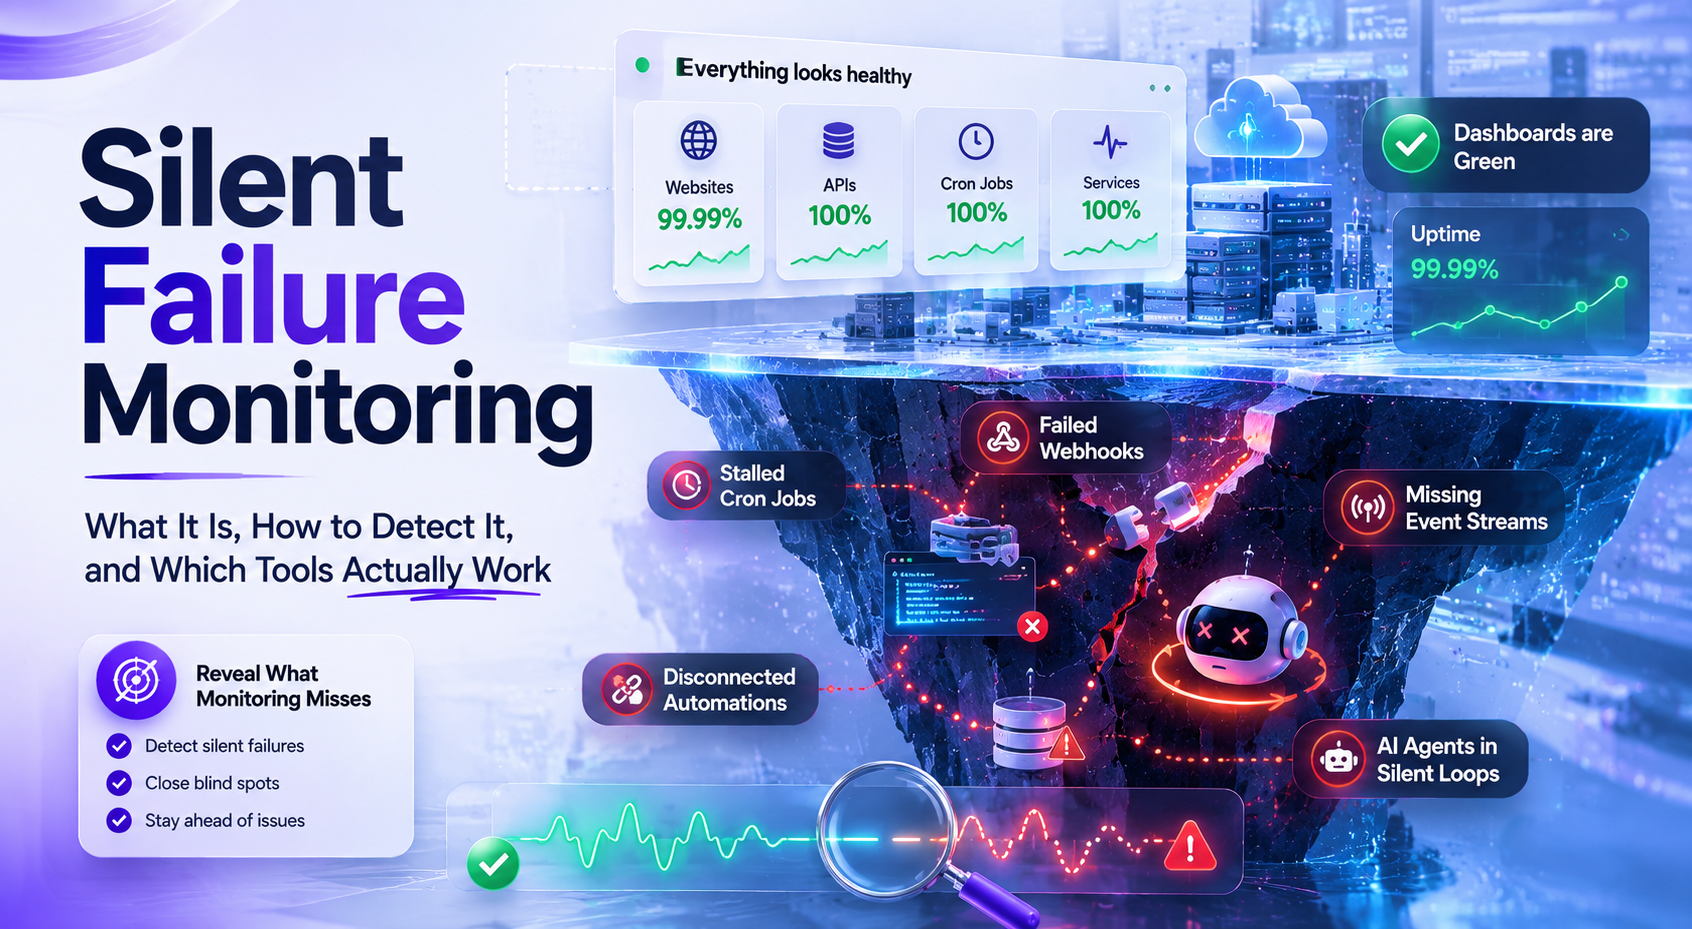
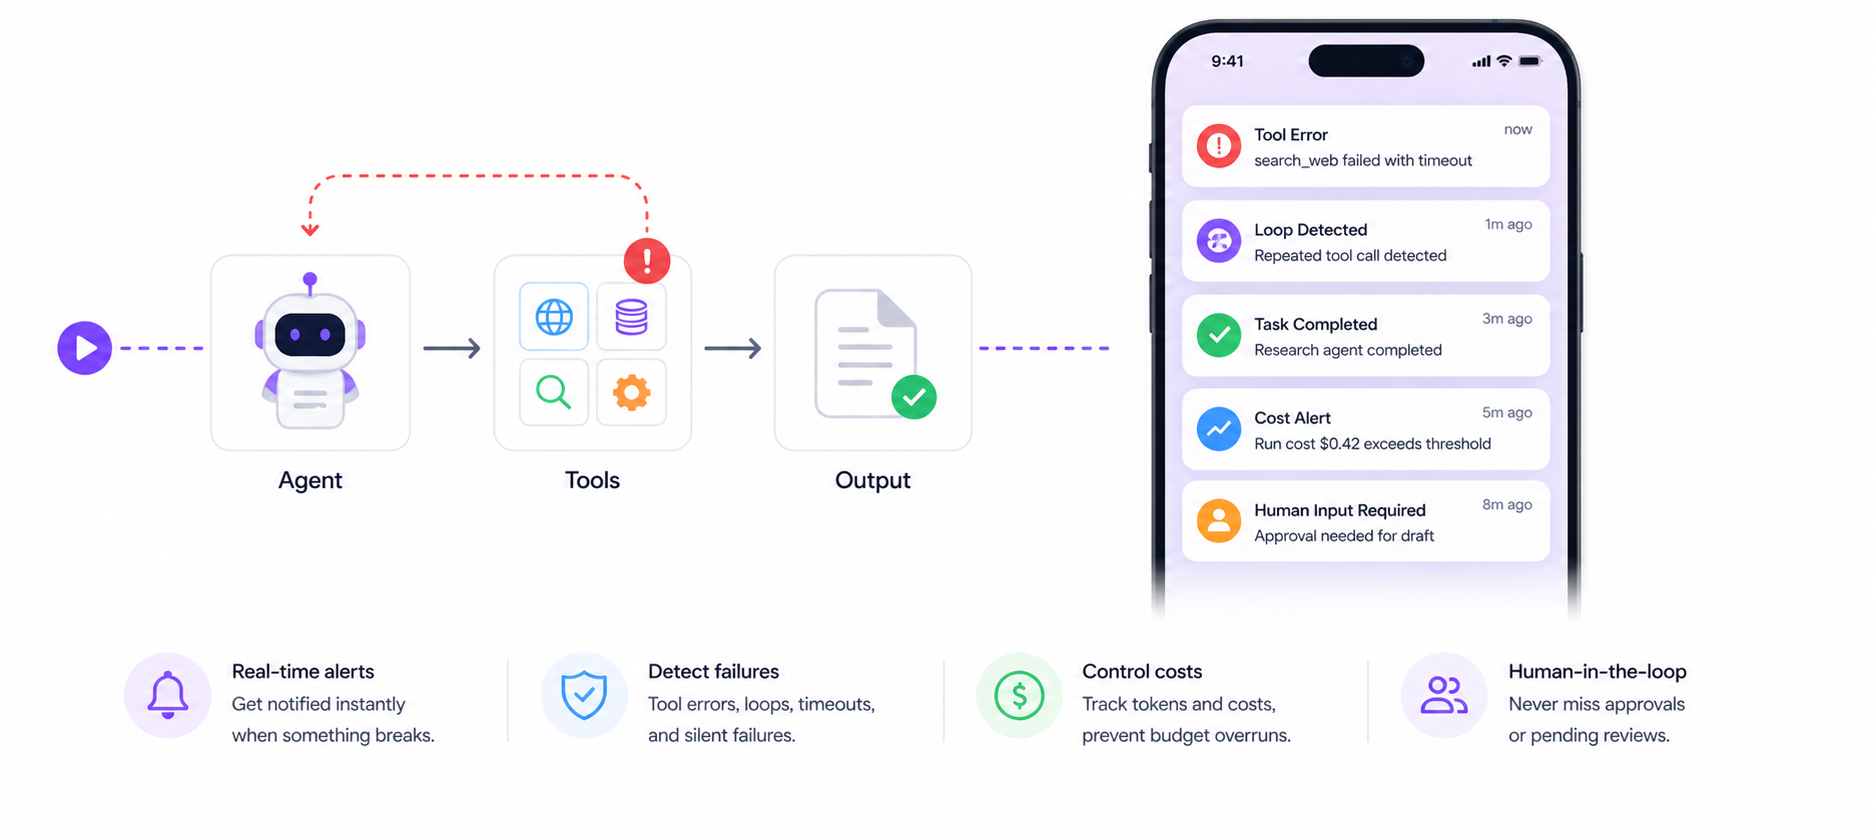
Silent failures don't throw exceptions. They don't create incidents. They just quietly cost you money until someone notices. This is the complete guide to understanding, detecting, and monitoring every type of silent failure in production.
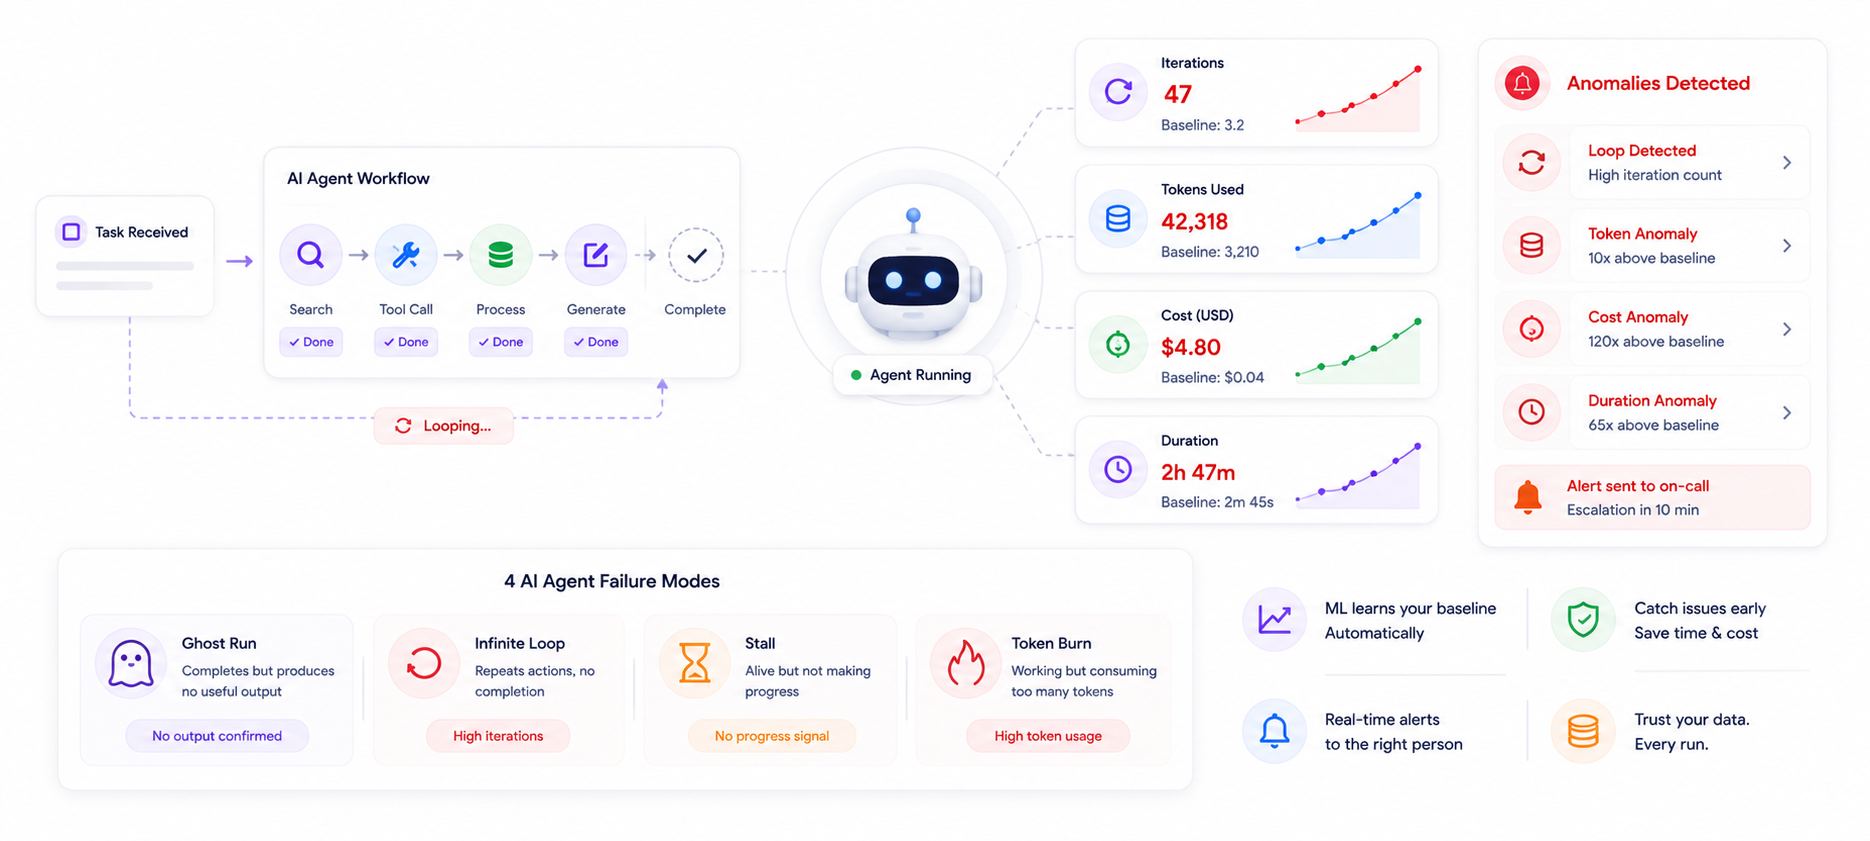
There are two questions you can ask about an AI agent running in production. Is it running? And is it working? Most monitoring stacks answer the first well. None of them answer the second.
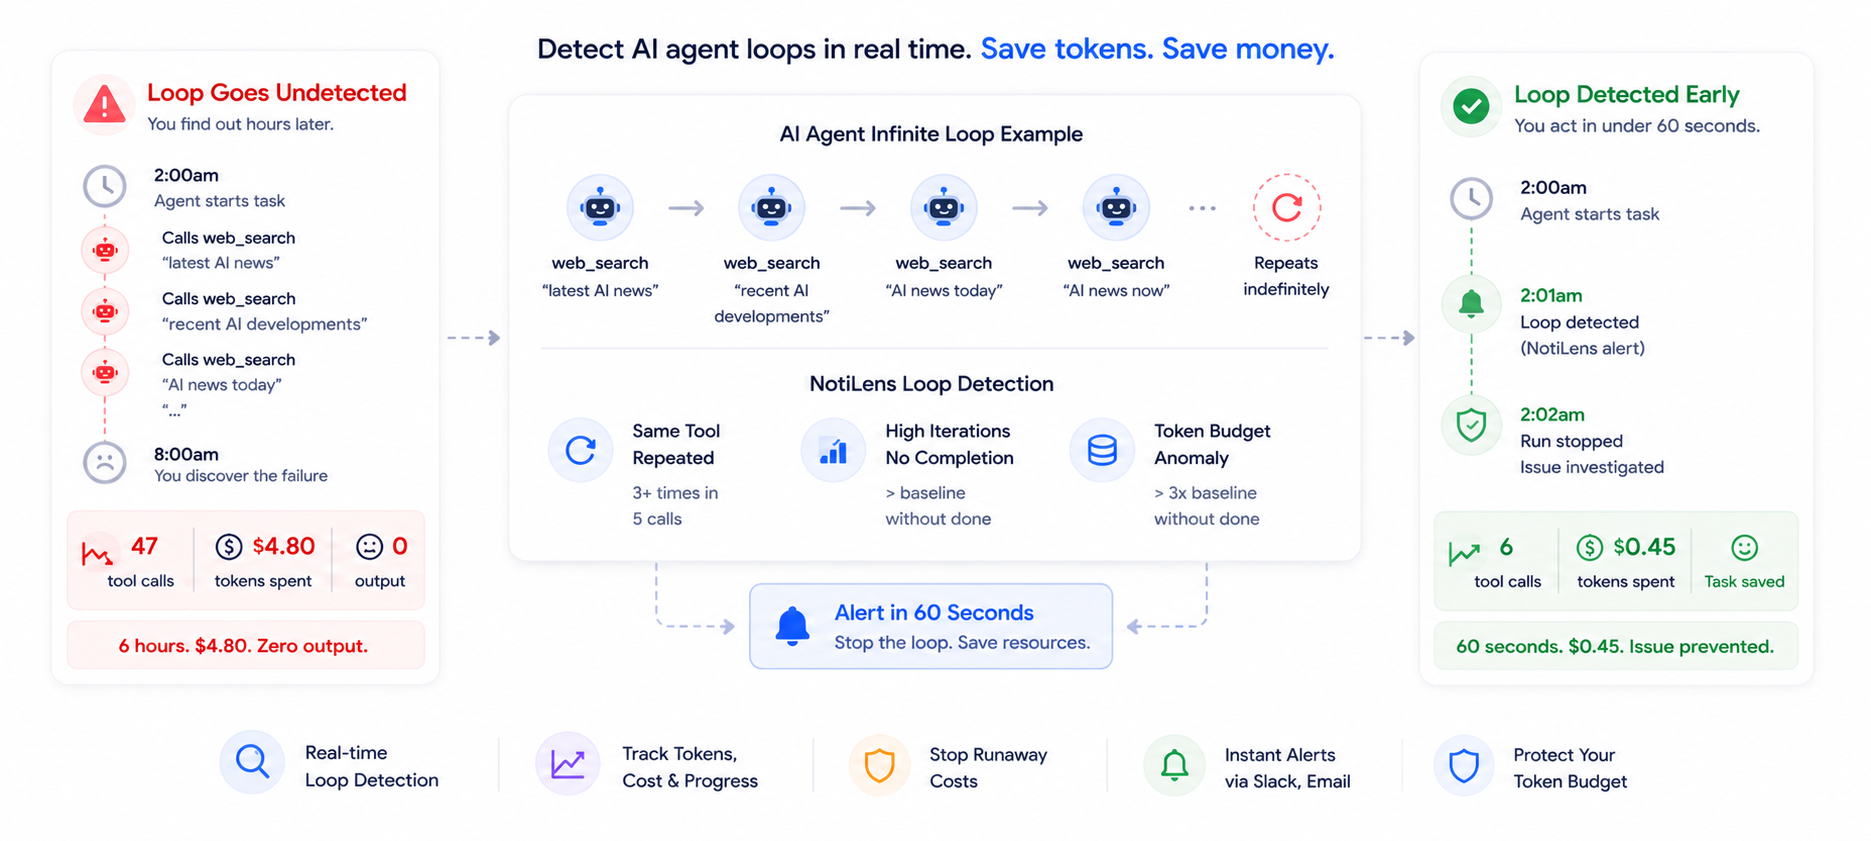
AI agent infinite loops don't throw exceptions. They look like normal activity — tool calls firing, tokens consuming, the process alive — until the budget is gone and the output is empty. Here's how to detect and stop them in real time.
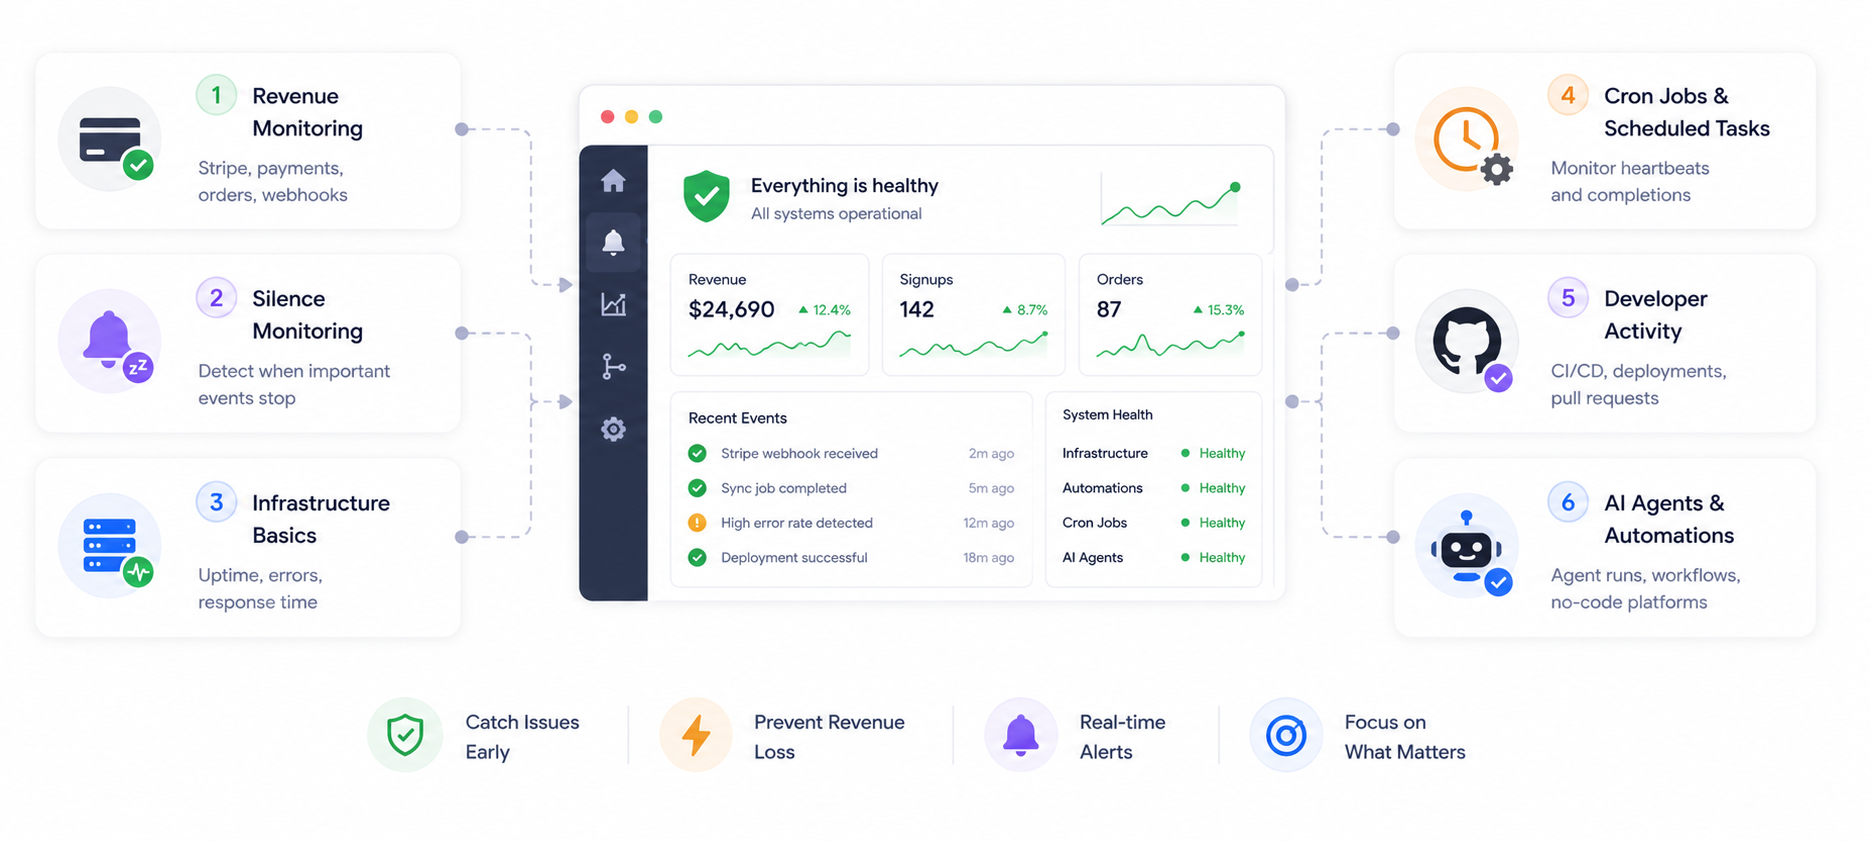
You're a founder. You don't have an SRE on call at 2am. You have a laptop, a Slack, and the vague anxiety that something is quietly breaking right now. Here's the monitoring stack I wish I'd had from day one.
AI agents fail differently from regular software. They don't crash — they drift, loop, stall, and consume resources while producing nothing. This guide covers the two failure modes unique to agentic AI and how to monitor for both.
LangChain agents fail silently in production — tool errors, infinite loops, stalled chains, cost spikes. Here's how to add real-time monitoring and alerts to any LangChain agent in under 10 minutes.